Best Testsigma Alternatives in 2026: Who Maintains the Tests?
Most Testsigma alternatives move the locator upkeep to a new login. Eight options for 2026, sorted by who keeps the tests working after you switch.
If the healer is why you’re leaving Testsigma, the next tool will disappoint you. Testsigma’s Atto agents already repair broken locators. So do most tools on the usual shortlist, and free Playwright has shipped a healer agent since October 2025.
What a switch can change is where your locators live and who edits them when the UI moves. That is the difference to buy on, so each tool below is compared on it, with a pick for every reason you might be leaving.
What you’ll learn
- The three reasons to look past Testsigma, from its own docs, GitHub and G2 reviews
- Who edits the tests after you switch, tool by tool
- What each tool does when a locator breaks, and who approves the fix
- Which alternative fits which reason for leaving, Pie included
Three Reasons to Look Past Testsigma
Testsigma isn’t short on features, and its reach goes well past the web into mobile and enterprise apps. The reasons to look elsewhere are narrower, ranked here by how many teams each one reaches.
- Locator upkeep: Every Testsigma step that touches the UI points at an element saved in its Elements repository, stored as an XPath, CSS or similar locator. When one breaks, auto-healing finds a working locator mid-run and holds it as a pending heal until a person approves it. The repairs turn into approvals, and the pile grows with every element someone saves.
- Slower runs as suites grow: G2 reviewers praise Testsigma’s ease of use and support. The review summary also flags slow performance on larger test suites, with longer waits for results (16 mentions), and a steep learning curve for new users when training is thin. Run a trial on a suite close to your real size before you commit.
- A community edition that stopped releasing: The Apache 2.0 edition is still on GitHub, but its last release, v3.0.1, shipped in August 2023. Two people asked in its discussions in 2025 whether the project was still alive, one after trying to build it and finding the backend service unavailable. Neither question has a reply. For teams that picked Testsigma to self-host, that is the risk to weigh.
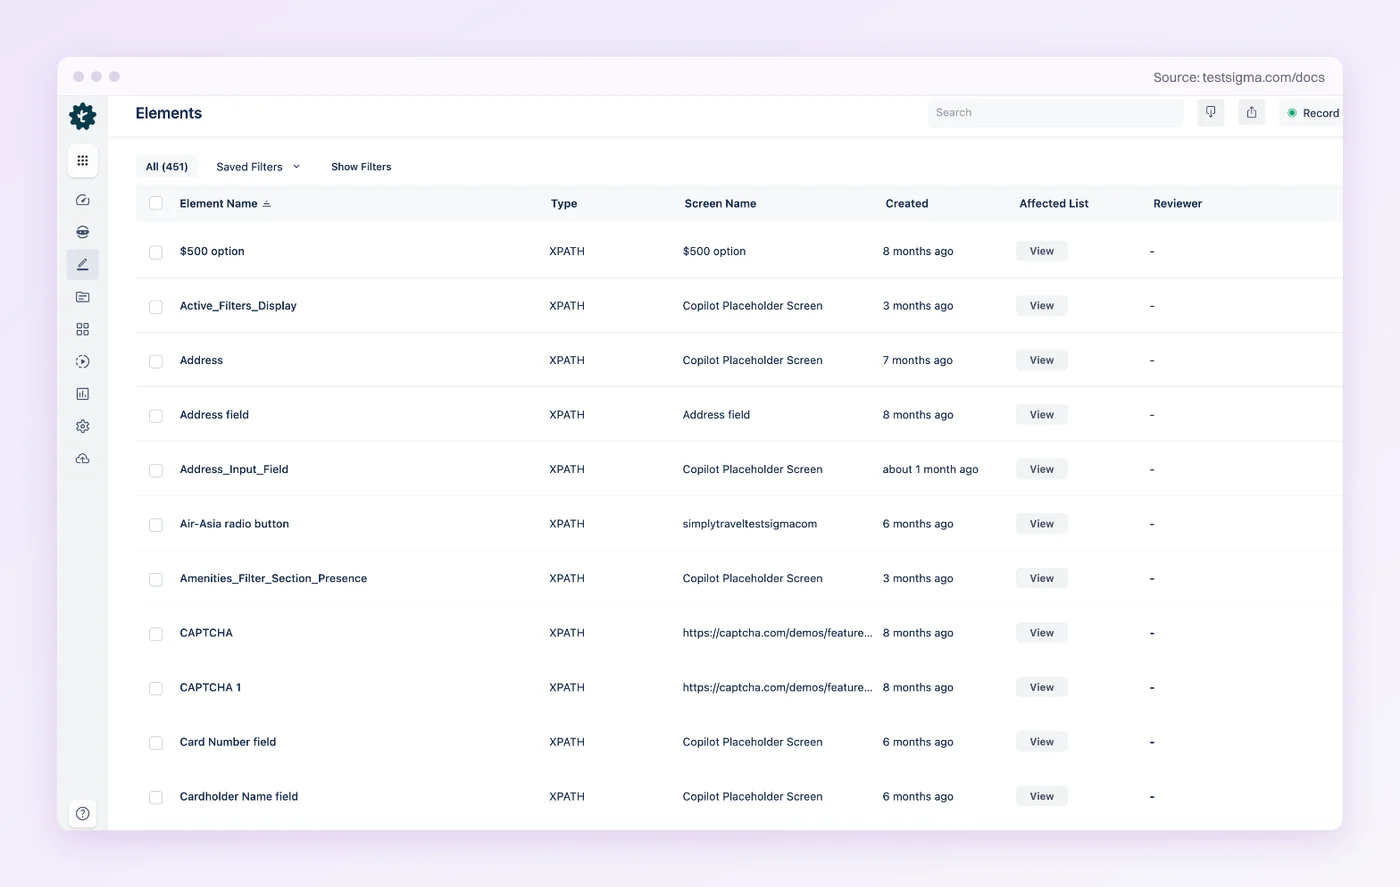
The second and third reasons are particular to Testsigma’s platform and release history. The first one travels with you. Upkeep scales with the number of saved locators, because each one assumes the page still looks the way it did when someone recorded it. Every alternative below ships some form of self-healing in test automation, so moving to another tool that heals stored locators buys a better mop for the same leak.
Eight Testsigma Alternatives at a Glance
Every product in this table uses AI somewhere in writing or repairing tests, which is why lists of the best test automation tools make them look interchangeable. An engineer at a 20-engineer startup spent a month looking at tools, Testsigma and Katalon among them, and told us how he sorts the market. His first tier records and replays tests, and his second heals a recorded test when the UI changes. The third generates tests on its own by scanning the app.
Read the “Who keeps them working” column first. It tells you who is editing tests six months after you switch.
| Tool | How tests get written | Who keeps them working | Platforms | License and plan |
|---|---|---|---|---|
| Pie | Agents generate; plain English for named flows | Pie’s agents run; you edit intended changes | Web, iOS, Android | Commercial, custom quote |
| testRigor | Typed, recorded or AI-generated English | Your team, in English | Web, mobile, API; Windows on paid plans | Commercial, free public plan |
| Katalon | Recorder, keywords or Groovy; TrueTest drafts | Your team approves locator swaps | Web, mobile, API, Windows | Commercial, free Studio |
| mabl | Trainer recordings plus Active Coverage agent | Your team, with auto-heal | Web and API; mobile add-on | Commercial, custom quote |
| Testim | Recordings plus JavaScript steps | Your team, via branches and reviews | Web; mobile sold separately | Commercial, free Community plan |
| BrowserStack | Recordings an AI agent reviews | Your team, AI healing on Pro | Web and mobile device cloud | Commercial, free trial |
| Functionize | Studio agents build them on the live web app | Studio’s agents repair them | Web browsers | Commercial, free plan |
| Playwright | Code; optional planner, generator, healer | Your engineers, in your repo | Chromium, Firefox, WebKit | Apache 2.0, free |
In six of these rows, a person or a person’s repository sits between a UI change and a passing test. Functionize Studio and Pie are the two where agents build the suite. Functionize describes Studio as a web testing agent, while Pie also generates tests for native iOS and Android apps.
What Happens When a Locator Breaks
Every tool here says it heals, so the useful question is what a heal may change before a person sees it. The table follows each vendor’s own documentation, with Pie first and Testsigma as the baseline. Testim and Functionize Studio are left out because their public pages don’t lay out these steps.
| Tool | Step is tied to | When it stops matching | Who approves | Safeguard |
|---|---|---|---|---|
| Pie | A plain-English step | Reads the screen; a moved button can need no repair | Your team edits steps for intended changes | A screenshot of every step |
| Testsigma | A saved XPath or CSS locator | Auto-healing swaps in a working one mid-run | A person approves it as primary | Primary changes only on approval |
| testRigor | Visible text, then attributes | Synonyms bridge small label changes | Your team; the English is the test | Vision AI healing is opt-in |
| Katalon | A test object’s stored locators | Tries its other locators, then an AI step | A tester approves the suggested swap | Old locator stays default until approved |
| mabl | A recorded element and its attributes | Auto-heal updates the locator; recovery tries a rescue | Auto-heal applies itself; your team decides on recovery | Recovery fails the test by default |
| BrowserStack | Element attributes from recording | Rule-based match, then AI healing on Pro | Your team, from results and healing logs | Docs warn a heal can pass over a real issue |
| Playwright | Locators in your test code | Healer agent proposes a patch and re-runs | Your engineers, in the repo | Skips a test if the feature looks broken |
Read the last two columns together. A heal that keeps a run going is fast, and it’s also the one place a broken button can turn into a green test. BrowserStack’s self-heal docs say as much, and Playwright’s healer agent skips a test rather than patch around a feature it thinks is broken.
The order of the heal matters too. A QA lead running a six-person team on a web-only product suite told us what his proof of concept with a couple of self-healing tools turned up. The tools advertised that they didn’t depend on XPath or CSS, yet in use they leaned on those locators and healed only when they stopped matching. Three or four test cases took 30 to 35 minutes, which he called a deal breaker for a regression suite of more than 700.
Before you sign, break one locator on purpose in each finalist and watch who gets asked to approve the fix.
8 Best Testsigma Alternatives in 2026
Ours goes first. The other seven run from the closest like-for-like swap to the furthest, and each entry answers the same question, who keeps the tests working after the switch. Playwright stands in for the code frameworks, since Selenium, Cypress and Appium leave you the same ownership. Agent-first products such as Momentic and QA Wolf sit nearer Pie’s model than Testsigma’s, so they live in our AI test automation tools roundup instead.
1. Pie: Tests Generated From the Running App
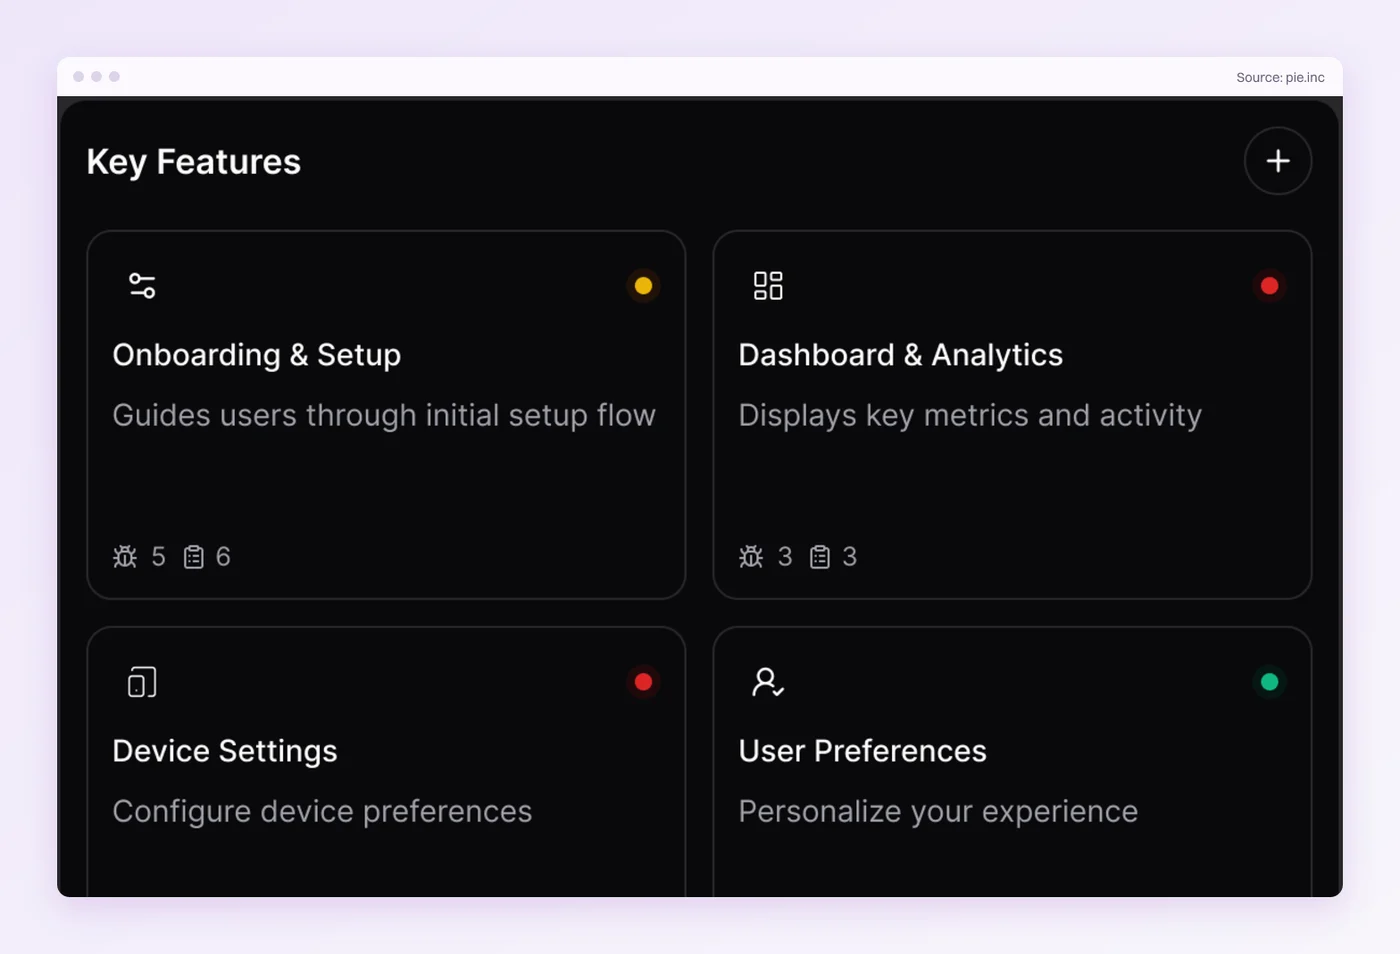
Pie is the agentic testing platform we build, and its answer to this list’s question starts before any test exists. Give it a staging URL or a mobile build and a test login. Its agents explore the flows they can reach and generate test cases, ranked by how critical each flow is. The first suite exists before anyone on your team writes a step.
Autonomous discovery covers that first suite, and upkeep is where the model differs. Your team authors supported tests without writing or maintaining selectors, on the web and in native apps, which run on iOS simulators and Android emulators, with real devices available on demand. Execution is vision-first, so a recognizable button that moves can need no locator repair. A deliberate redesign is different. Your team re-runs the affected tests and edits the steps the change was meant to alter.
For one specific flow, write a plain-English custom test, and bring the test cases you already keep across as a CSV. Where Pie has access to your repo and fix pull requests are switched on, Pie Loop can draft a fix for a regression it caught and open it for your team to review.
- Who maintains the tests: Pie’s agents generate them and re-run them on demand or on the builds you configure. Your team reviews what they find and edits steps when behavior changes on purpose.
- Rating: 5.0/5 from 3 reviews on Gartner Peer Insights.
- Pricing: Custom pricing, tailored to your team’s requirements and testing volume. Contact Pie for a quote.
- Limitation: Load and security testing, and hardware checks such as Bluetooth pairing, need their own tools. iOS uploads are simulator builds.
- Best for: Teams shipping web and native mobile apps who want regression coverage without curating selectors.
- Not for: Engineers who want every test as code in their own repo.
2. testRigor: The Closest Swap for Plain-English Authors
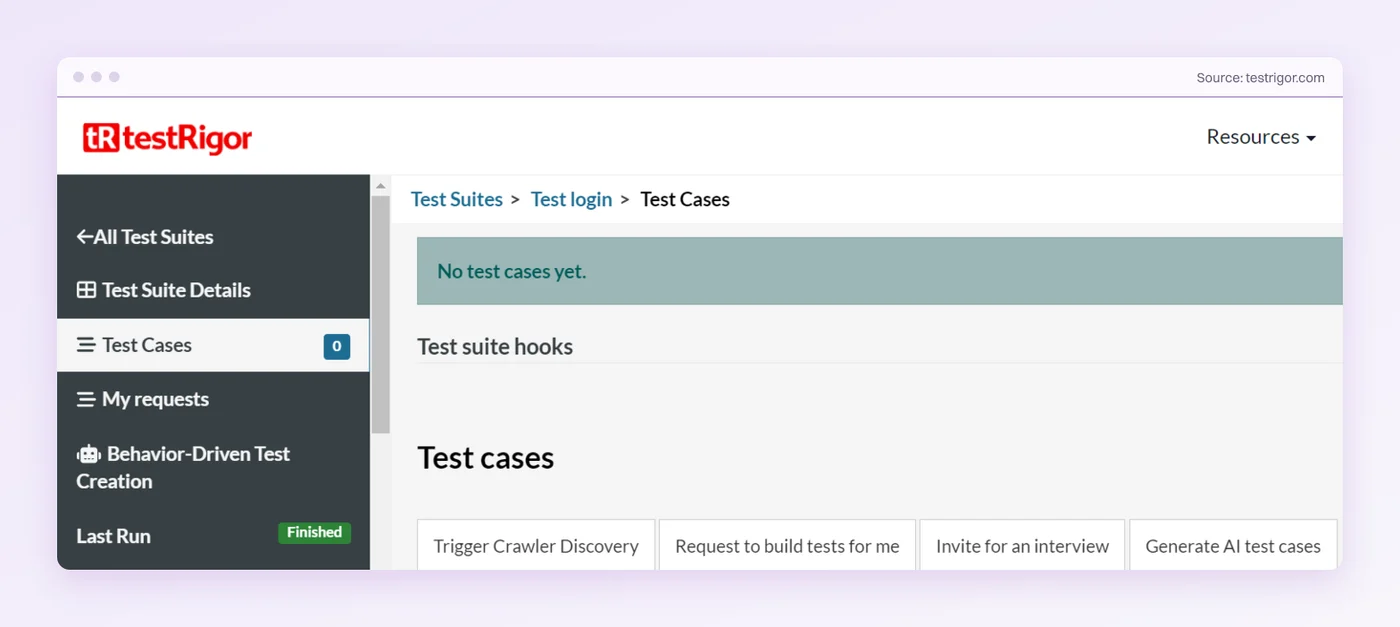
testRigor is the nearest swap for a team that likes writing tests in plain English. A step reads like an instruction, such as click "Sign in", and testRigor matches visible text on the page before it falls back to attributes like test ids. Paid plans add native Windows desktop apps to its web and mobile coverage.
The trade is that the English is the test. A renamed button label gets bridged by synonyms, which are on by default, or by Vision AI healing once you switch it on. Your team can also write alternatives into the step. Someone on your side writes or approves every test and keeps the wording in step with the product, which is the ownership question our testRigor and Testsigma comparison takes apart.
- Who maintains the tests: Your team, in plain English, with synonyms covering small label changes.
- Rating: 4.6/5 from 47 reviews on G2.
- Pricing: Free if your tests and their results can be public. Private plans start with a 14-day trial, and Enterprise is custom-priced.
- Limitation: The free plan makes your tests and results public, and native Windows desktop testing needs a paid plan.
- Best for: QA teams whose manual testers should write and read the automation.
- Not for: Anyone hoping to stop owning the wording of every test.
3. Katalon: Low-Code Breadth With a Scripting Escape Hatch
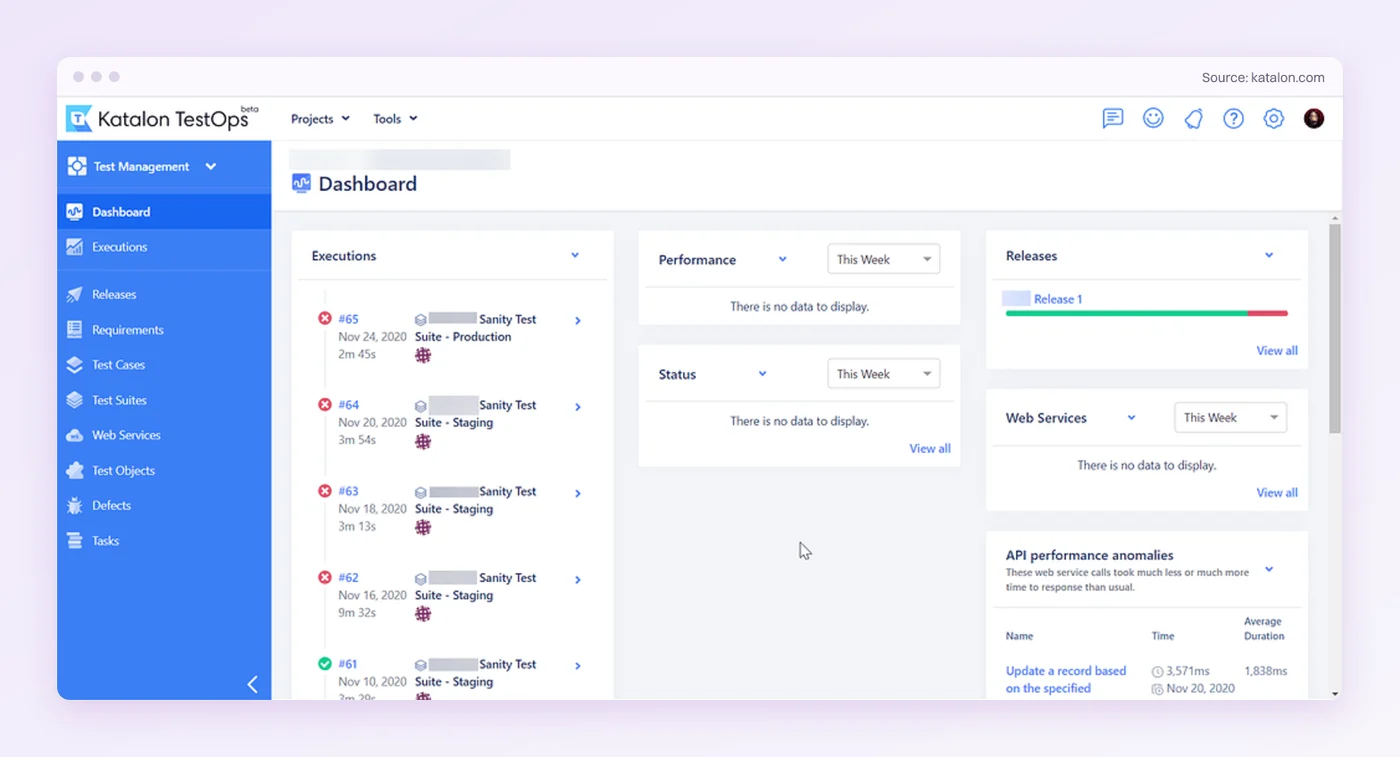
Katalon fits teams whose problem with Testsigma is control more than upkeep. Katalon Studio holds every test type it supports in one project, Windows desktop included. A test can start as a recording or built-in keywords and drop into Groovy when a flow gets hard. TrueTest proposes test cases from anonymized production sessions, and your team approves each one before it joins a suite.
Each recorded step points at a test object with stored locators. When the default fails, classic self-healing tries the object’s other locators, then hands off to an AI step that reads the page. After the run, Katalon suggests the locator that worked, and the old one stays the default until a tester approves. In our Testsigma and Katalon breakdown, your team keeps the tests working in both tools.
- Who maintains the tests: Your team, through Studio’s test objects and scripts, approving each locator swap the healer suggests.
- Rating: 4.4/5 from 228 reviews on G2.
- Pricing: A free Studio tier for authoring and running tests locally, Professional at a $2,199 list price per seat per year, and a quoted Enterprise plan, per Katalon’s pricing page.
- Limitation: Classic healing only falls back to locators already stored on the object, so anything new goes to the AI step or to a tester.
- Best for: Mixed-skill teams wanting one vendor across app types, with code on tap.
- Not for: Shops trying to retire locator upkeep entirely.
4. mabl: Low-Code Cloud Testing With Cautious Recovery
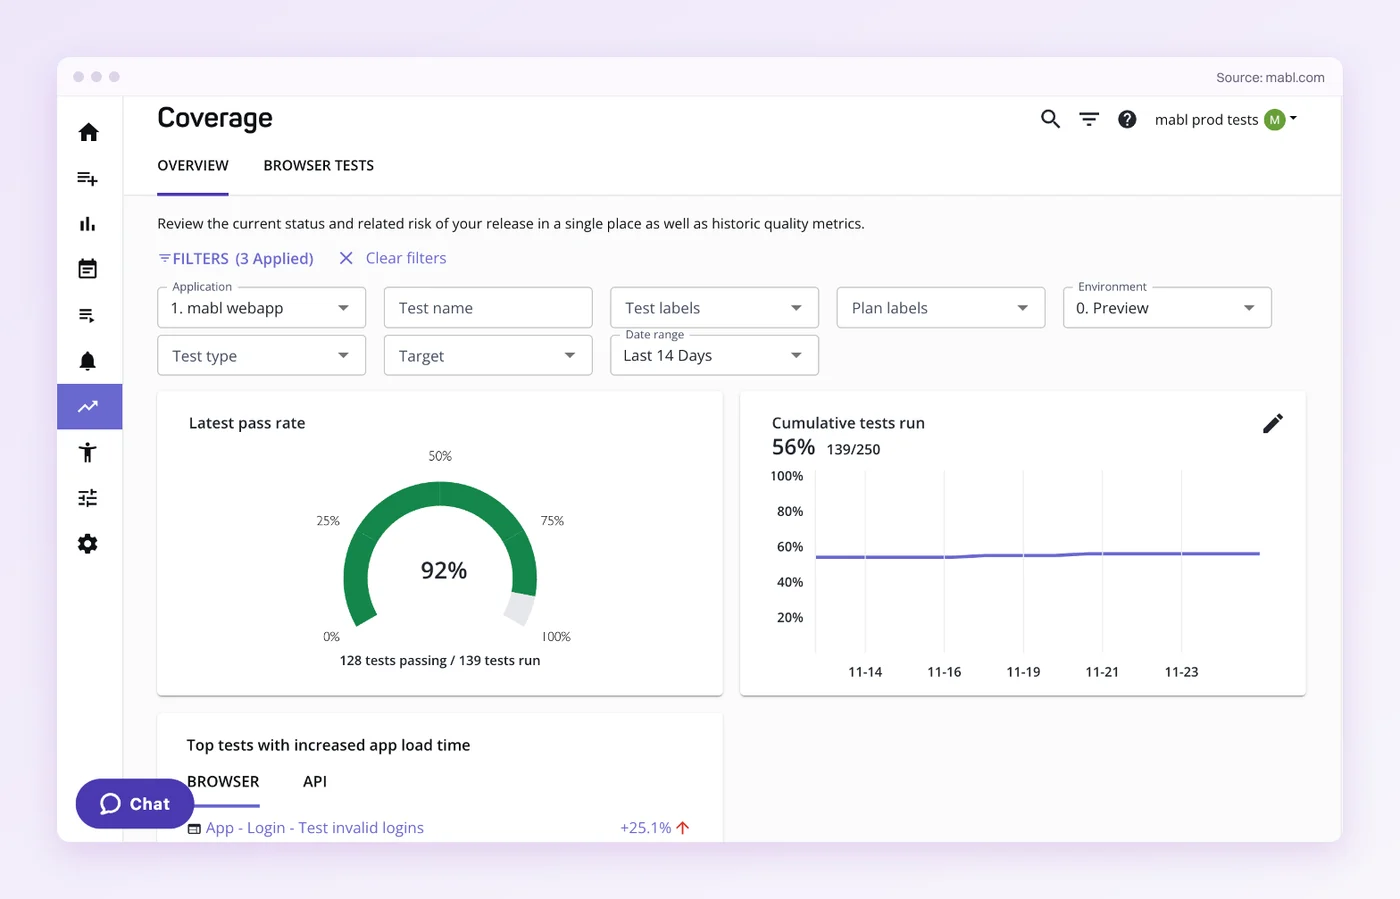
mabl suits teams that want accessibility and performance checks riding on the same functional tests, in one cloud platform. Tests start in its low-code Trainer. Since April 2026 its Active Coverage agent also generates tests in the cloud and tries to recover failing runs.
The recovery is the careful part. Out of the box, mabl attempts a recovery and logs it, but marks the test failed until your team chooses to let recovery pass it. At the element level, auto-heal uses visual context and several recorded attributes to find a drifting element, then updates its locator. Underneath, every step is bound to an element mabl recorded, so this is Testsigma’s model with one difference: auto-heal updates locators on its own, and the care sits in recovery, which still fails the test.
- Who maintains the tests: Your team, with auto-heal updating locators and recovery that fails safe by default.
- Rating: 4.4/5 from 40 reviews on G2.
- Pricing: Custom quote, with cloud runs billed in credits, local runs free and a 14-day trial, per mabl’s pricing page.
- Limitation: Mobile App Testing sits under Add-Ons on mabl’s pricing page rather than with the base platform, so confirm what your quote includes.
- Best for: QA leads who want accessibility and performance checks on top of their functional tests.
- Not for: A team that wants out of element records altogether.
Skip the Locator Library
Hand Pie a staging URL. Get back tests nobody on your team wrote.
5. Testim: Recorded Tests That Change Through Review
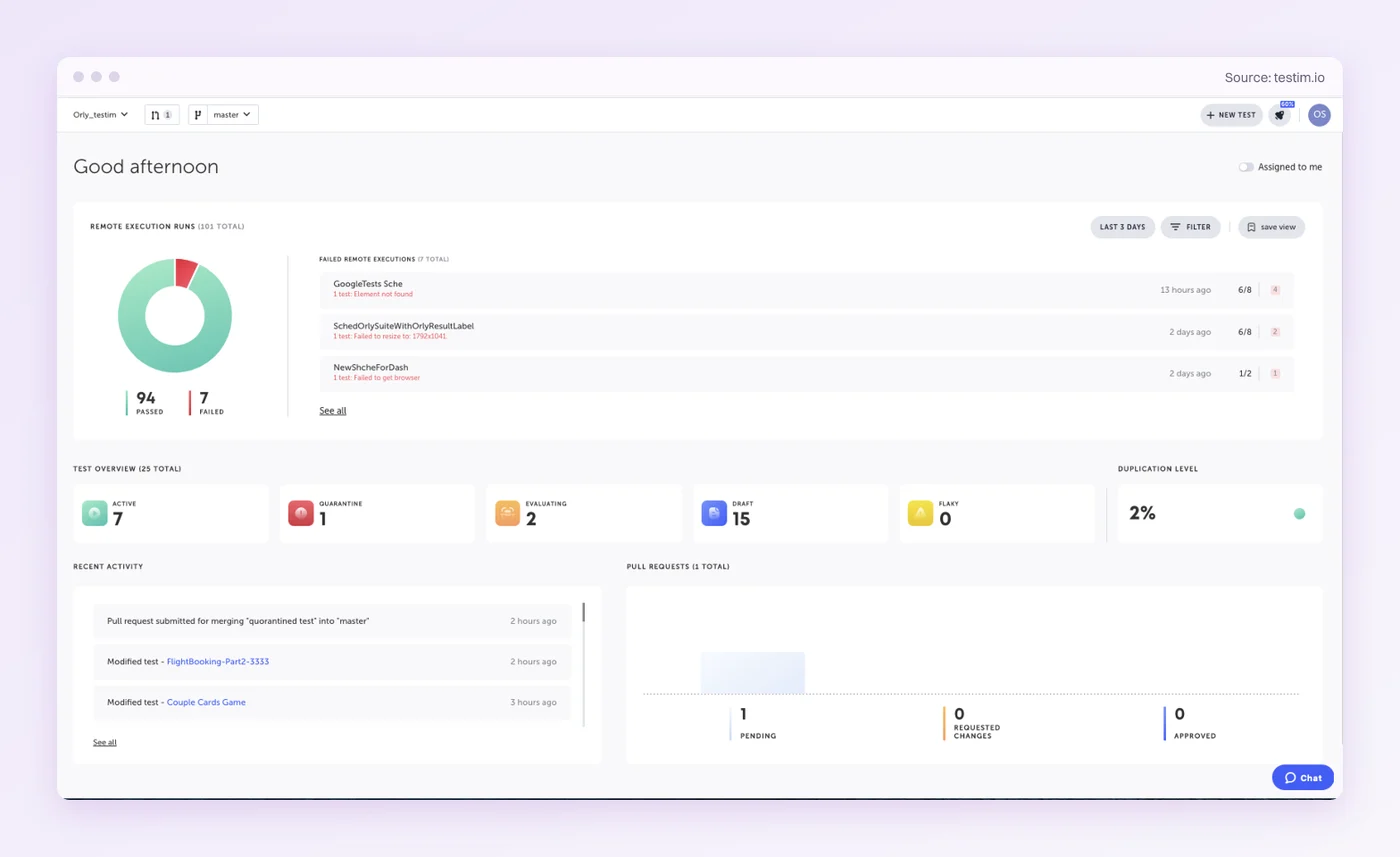
Testim, a Tricentis product, captures web flows with an AI-assisted recorder whose smart locators adjust as the page changes. Logic the recorder can’t express goes into JavaScript steps, and Testim Copilot can draft that code from a description.
Its ownership model is the most explicit on this list. Tests live on branches, and on the Pro plan an edit can go through a pull request that an authorized reviewer approves, the way code does. Native apps need Testim Mobile, which Testim sells as its own product.
- Who maintains the tests: Your team, through branches and reviewed pull requests.
- Rating: 4.5/5 from 53 reviews on G2.
- Pricing: Testim Web drops to a free Community plan after its trial, and the paid Web, Mobile and Salesforce plans are quoted.
- Limitation: Pull-request review is a Pro-plan feature, and native mobile is a separate purchase.
- Best for: Engineering-led teams on dynamic web apps who review test changes like code.
- Not for: QA teams who want web and native mobile apps under one product.
6. BrowserStack Low Code Automation: Breadth of Browsers and Devices
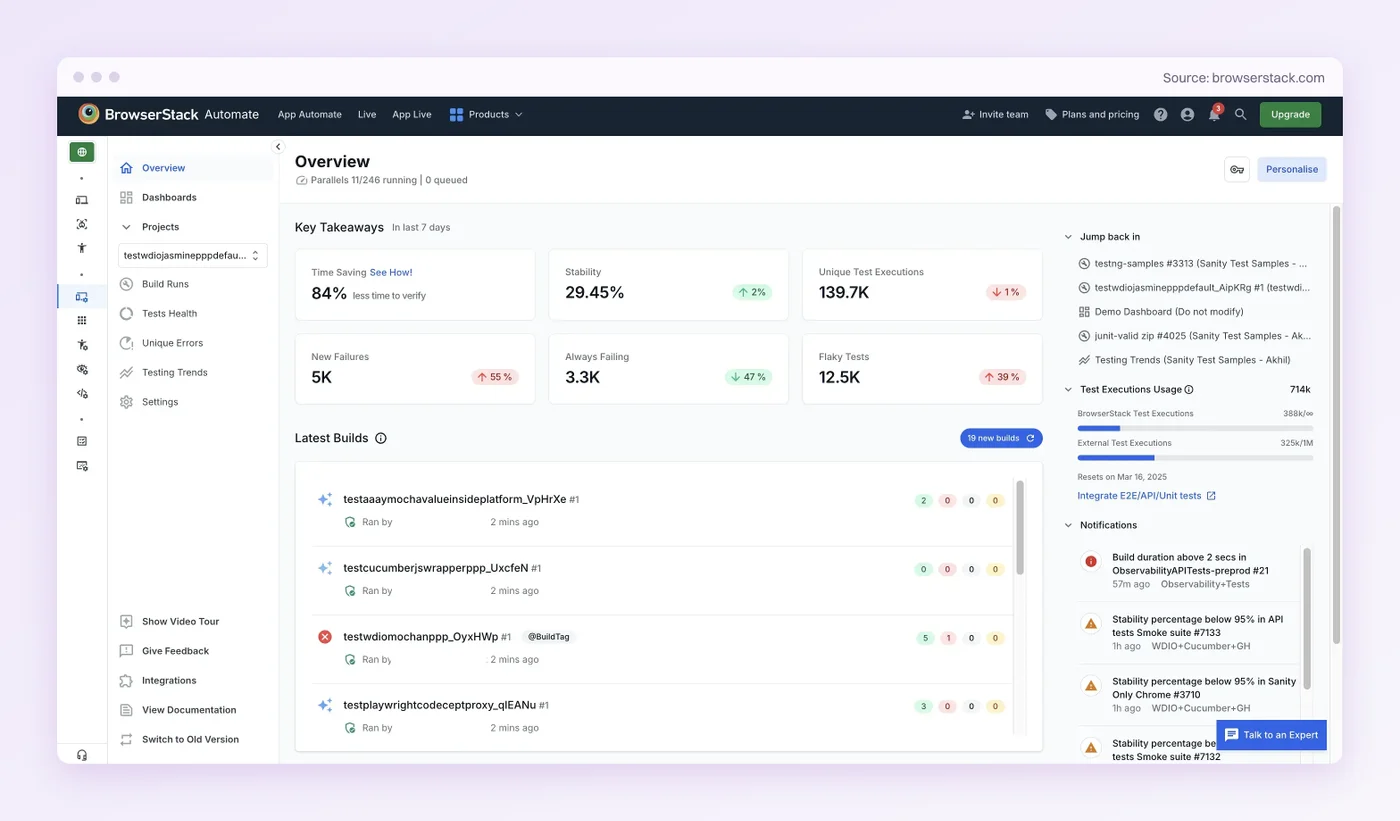
BrowserStack is on this list for its infrastructure. Low Code Automation turns a recorded flow into a test, and an AI agent reviews and corrects it before saving. Suites run across real desktop and mobile browsers on BrowserStack’s cloud, which matters most when a bug lives on one phone and nowhere else.
When a step stops matching, a rule-based pass tries the attributes captured at recording, and AI self-healing takes over on the Pro plan and above. Testsigma already runs tests on its own cloud of browsers and real devices, so device access alone isn’t a reason to switch.
- Who maintains the tests: Your team, with AI self-healing on Pro plans and above.
- Rating: 4.4/5 from 3,362 reviews on G2, listed under BrowserStack.
- Pricing: Quoted through sales, with a free trial. AI self-healing needs Low Code Automation Pro or above.
- Limitation: BrowserStack’s own docs warn that a heal can adjust a step and let a test pass while the app has an underlying issue.
- Best for: Teams chasing bugs that only reproduce on particular phones or browsers.
- Not for: Teams that already have the devices they need and lose their hours to repairing tests.
7. Functionize: Studio Hands Web Test Upkeep to Agents
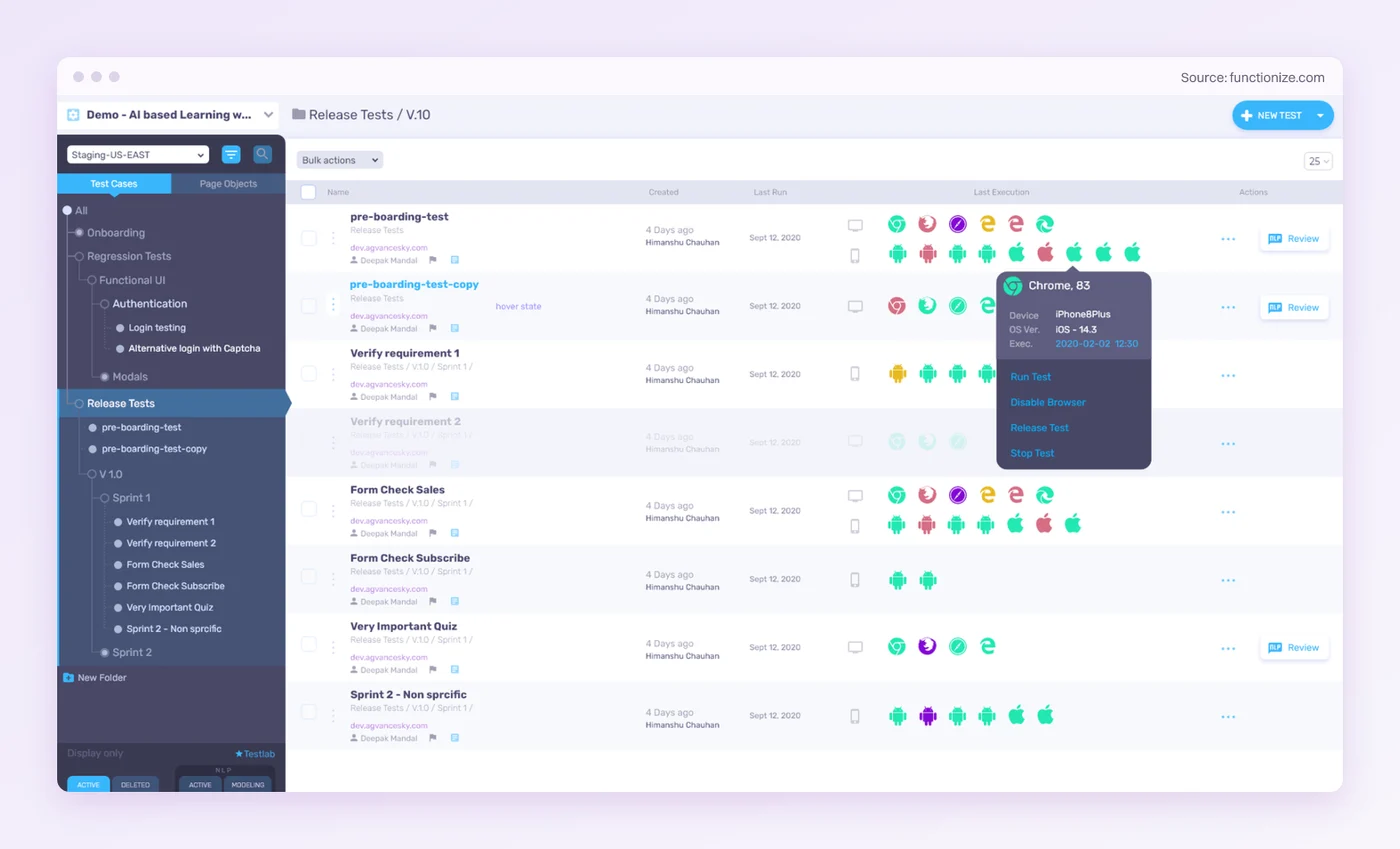
Functionize’s classic product paired natural-language authoring with ML-based healing for enterprise suites. In July 2026 it launched Studio, where agents build their own tests against the live web app and repair them as it changes. Studio runs in Chrome, Firefox, Safari and Edge. A coding agent can drive it over MCP.
Studio is the closest model here to Pie’s, since agents rather than your team build the suite. The difference is scope. Functionize describes Studio as a testing agent for web UI workflows, so confirm native support before a mobile team plans around it.
- Who maintains the tests: Studio’s agents build and repair them, for web apps.
- Rating: 4.6/5 from 11 reviews on G2.
- Pricing: A free plan, Growth at $20 a month, Scale at $100 a month and a quoted Enterprise plan, per Functionize’s pricing page.
- Limitation: Functionize positions Studio for web UI workflows, and its public pages don’t mention native iOS or Android testing.
- Best for: Web-only teams that want agents to build and fix their browser tests.
- Not for: Mobile teams, until Studio documents native app support.
8. Playwright: The Free Framework You Own in Code
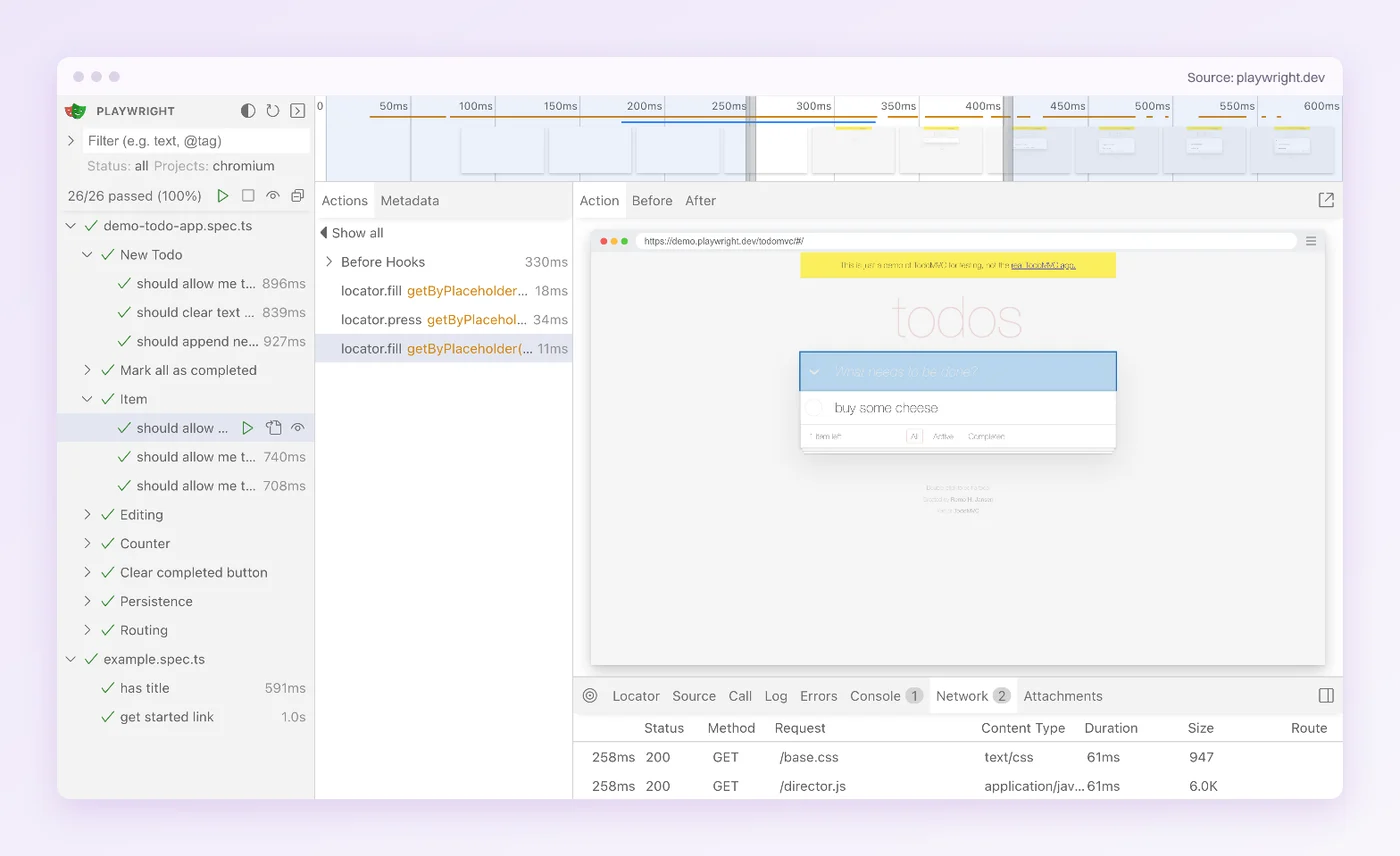
Playwright answers a different complaint, that you’d rather own tests as code. It’s an Apache 2.0 project maintained by Microsoft, and one API drives all three major browser engines. Since version 1.56 it has shipped test agents that run inside AI coding tools such as Claude Code and VS Code, and one of them is a healer.
The healer replays a failing test against the current page and proposes a patch, such as a new locator or a longer wait. If it decides the feature itself is broken, it marks the test skipped instead. Every test and every locator lives in your repo. It’s the right trade for an engineering team and the wrong one for a QA team that picked Testsigma to stay out of code.
- Who maintains the tests: Your engineers, in code, with an optional healer agent.
- Rating: 4.8/5 from 14 reviews on G2.
- Pricing: Free and open source. You pay for CI machines, plus whatever AI coding tool and model the agents run in.
- Limitation: A healer patch is a code change your engineers review and keep, and someone has to find out why a test was skipped.
- Best for: Engineering orgs that version and review tests alongside product code.
- Not for: QA teams that can’t spare engineering time for the suite.
Match the Alternative to Your Reason for Leaving
Start from the reason you’re leaving, then pick the tool built for that reason.
- Locators eat the week: Pie generates the suite from the running app, and your team authors supported tests without writing or maintaining selectors.
- Breadth plus scripting: Katalon keeps every app type in one project, with Groovy for the hard flows.
- Plain-English authors: Pie turns a plain-English description into a custom test for any flow you name, and testRigor keeps every test readable for manual testers.
- Accessibility and performance too: Pick mabl, which adds both checks to the functional tests you already run.
- Code-review discipline: Testim’s Pro plan sends each test edit through a reviewed pull request, and Pie, with fixes switched on, opens its proposed fixes as pull requests your team reviews.
- Hardware-specific bugs: BrowserStack puts each recorded test on the exact phone or browser where the bug lives.
- Agents for the tests: Pie’s agents build the suite across web and native mobile, and Functionize Studio does it for a web-only app.
- Engineers who want code: Playwright, with its healer agent taking the first pass at broken tests.
- Web and native mobile together: Pie covers both from one platform, and your team reviews findings instead of curating selectors.
Shortlist two, then run the broken-locator check from the table above on both.
Stop Relabeling the Maintenance
Look, Testsigma’s healer works. So do most of the healers on this list, which is why a new one won’t change who does the work.
Decide what you want to stop doing. Missing devices and the wish to own code have tools that fix them. If upkeep is the problem, moving between healers only relabels it, because every saved locator is a bet that the page won’t change.
We built Pie so your team stops placing that bet. Its agents generate the tests from the running app, and your team spends its time on the judgment calls. Point it at a staging build this week and read what comes back.
Stop Repairing Locators
Send a staging URL or a build. See the regressions Pie catches.
Frequently Asked Questions
testRigor suits plain-English authors, and Katalon suits mixed teams that want scripting. mabl, Testim and BrowserStack keep the low-code model.
Functionize Studio hands web tests to agents, and Playwright suits engineers. Pie's agents generate the tests, and your team authors supported tests without maintaining selectors.
Yes. Playwright and Selenium are free and open source for web apps, and Appium is the open-source option for native iOS and Android apps.
All three expect engineers to write the tests as code and keep every locator current in their own repository.
No. Its pricing page lists two quoted plans, Pro and Enterprise, and the site offers a free trial.
testRigor, Testim and Functionize list a free plan with limits, Katalon lists a free Studio tier for local authoring, and Playwright is free and open source.
Less than the switch suggests. Most low-code alternatives still tie each step to a stored element and patch it with a healer, so the upkeep moves with you.
Maintenance changes when the model changes, to tests you own as code or tests your team authors without maintaining selectors.
It can. BrowserStack's own documentation warns that a heal can adjust a step and let a test pass over an underlying issue.
The guards differ. Katalon waits for a tester to approve a locator swap, and mabl's runtime recovery marks the test failed until your team decides to trust it further.
For teams that want breadth and a scripting escape hatch, yes. Katalon Studio holds every test type it supports in one project, Windows desktop included, and a test can drop into Groovy when a flow gets hard.
Its healer suggests locator swaps that a tester approves.
Testsigma's agents help your team build and heal a suite whose steps point at stored locators. Pie's agents explore the running app and generate the tests, and your team authors supported tests without writing or maintaining selectors.
People on your team review findings and edit intended changes.
13 years building mobile infrastructure at Square, Facebook, and Instacart. Now building the QA platform he wished existed the whole time. LinkedIn →