How to Fix Flaky Tests: Detect Them, Fix the Root Cause, Stop Making More
Flaky tests multiply as AI writes more code. How to catch them before they block CI, fix the async, state, and order root causes, and stop making more.
Flaky tests caused as much as 21% of master build failures in Jira’s frontend, by Atlassian’s count. Its answer was a detection system that quarantines each flipping test and files it with the team that owns it, and that system has recovered more than 22,000 builds.
Your suite is smaller, but every test your team adds, or an AI assistant writes, is another chance to add one. Here is how to find the tests that really flip and fix each one at its cause.
What you’ll learn
- Why fixing flaky tests one at a time stops working
- How to detect flaky tests, triage them, and diagnose the root cause
- Code patterns that eliminate timing and state issues
- When to quarantine vs. delete vs. fix immediately
- Team workflows that prevent flaky test accumulation
Why Fixing Flaky Tests One at a Time Stops Working
Look, fixing flaky tests one at a time works only while you repair them faster than your team adds them. Adding a test costs its author almost nothing. A flaky one costs whoever hits the red build, and that cost never shows up in the commit that caused it.
On the platform team I was on, our job was pushing other teams to build test coverage. Getting the tests written was hard. Keeping them working afterward was the bigger pain. Two things now push the adding side up.
Reason 1: More Code Means More Tests
Satya Nadella said at LlamaCon in April 2025 that 20% to 30% of the code inside Microsoft’s repositories was “written by software”, though TechCrunch noted the methodology is unclear. Each new feature brings its own tests, and each test is one more place a flake can hide. Volume alone lifts your absolute flaky count, and the cost of flaky tests with it, even when the flake rate holds steady.
Reason 2: Assistants Copy the Flakiness They Can See
The second push is what those new tests look like. A 2026 ICSE SEIP study of LLM-generated tests for four database systems found a slightly higher share of flaky tests among the generated ones, and found that both models copied flakiness from the existing tests in their prompt context. Most of the flaky tests it found (72 of 115) assumed results would come back in an order the database doesn’t guarantee.
The study covered database-system tests, so for a UI suite it’s a warning rather than a measurement. If your suite is full of the patterns that make tests flaky, like hardcoded sleeps and shared fixtures, an assistant that reads it has plenty of flaky examples to copy.
You fix the ones in front of you first, and the rest of this guide shows how. But you also have to change how tests get created so fewer flaky ones get written in the first place.
Detect Them Before You Fix Them
Nothing else in this guide works until you can prove which tests are flaky, so detection comes first. Teams often start from memory, arguing about which tests “feel unreliable” in standup instead of pulling the numbers. Detection replaces the argument with data.
The baseline method is to rerun the suite, and it needs no special tooling. A test that passes and fails across repeated runs on the same commit is flaky by definition. Run the full suite, or one file at a time, several times and record which tests flip.
# Run the suite 10 times, record pass/fail each run
for i in {1..10}; do
  npm test 2>&1 | tee "run-$i.log"
done
How Many Reruns Are Enough
Ten runs is plenty for a loud flake and too few for a quiet one. If a test fails a share p of its runs, the chance that n reruns show at least one failure is 1 − (1 − p)n, so ten runs catch a test that fails one run in twenty only 40% of the time.
| Test Fails | Caught by 10 Reruns | Reruns for 95% Confidence |
|---|---|---|
| 1 run in 5 (20%) | 89% | 14 |
| 1 run in 10 (10%) | 65% | 29 |
| 1 run in 20 (5%) | 40% | 59 |
| 1 run in 100 (1%) | 10% | 299 |
Size the loop to the quietest flake you care about. For a checkout or login test, run the suspect file a few dozen times in a nightly job instead of ten times by hand.
Rerunning gets you started, but it does not scale to thousands of tests. At scale the detection has to run itself. Slack automated it and described the result in their flaky-test auto-detection writeup. Its system reads failed test results from CI runs, files a ticket, and opens a pull request that disables the test.
Many CI platforms now surface flaky tests natively. CircleCI identifies them on the Tests tab of its Insights dashboard, and Cypress Cloud detects and flags flaky tests from your recorded runs on its Team plan, with retries enabled. Tools built for test observability offer similar views across frameworks. Where your platform exposes this, turn it on before you write a single fix.
Rerunning finds the flaky tests you already have. A one-line search finds the ones waiting to happen, because every fixed sleep is a guess about timing.
# Count hardcoded waits in your test folder (adjust the path)
git grep -nE "sleep\(|waitForTimeout\(|cy\.wait\([0-9]" -- tests/ | wc -l
Detection produces the one input the rest of this guide depends on, a ranked list of the tests that flip, each with its failure rate. Triage picks up from there.
Triage: What to Fix First
Triage decides the order you work through the flaky list, and it’s an economics problem. You will not eliminate flakiness this quarter, so spend a fixed repair budget where it buys back the most trust.
Fix the high-blast-radius tests, quarantine the rest, and accept a small residual instead of chasing zero. A flaky checkout test deserves attention today. One that fails now and then on a deprecated admin page can wait.
Economic triage has one blind spot. It assumes a bounded backlog you can chip away at, and rising test volume unbounds it. When your suite adds flaky tests faster than you clear them, working the queue is a treadmill, so the prevention section below goes after the supply as well as the backlog.
Severity Matrix
| Impact | Frequency | Action |
|---|---|---|
| Critical flow checkout, auth | High 10% or more failures | Fix immediately, block deployment |
| Critical flow | Low under 10% failures | Fix within sprint |
| Non-critical | High | Quarantine, schedule fix |
| Non-critical | Low | Quarantine, review monthly |
Add the Prioritization Data
Triage ranks the backlog on four attributes, and detection already gave you the first:
- Failure rate: Failures divided by total runs over 30 days (from detection)
- Last code change: When was the test or its target code modified?
- Coverage scope: What user flows does this test protect?
- Fix complexity: Estimated hours based on root cause
Without this data, you’re guessing. Instrument your CI to record historical failure rates when it doesn’t already.
Diagnose the Root Cause Before You Touch the Test
Rerun the failing test under changed conditions, and the pattern of passes and failures points at the fix. GitHub’s flaky-test system works this way. It reruns each failed test three times, in the same process, with the clock shifted forward, and on a different host, because each scenario targets a different common cause of flakiness. You can run a by-hand version of the same diagnosis with the table below.
| What You See | Likely Cause | Where to Fix It |
|---|---|---|
| Fails at random even when run alone, usually on a missing element or stale text | Async wait | Fix 1: Replace Fixed Waits |
| Passes alone, fails inside the full suite | Shared state | Fix 2: Isolate Shared State |
| Passes or fails depending on test order or seed | Order dependency | Fix 3: Break Order Dependencies |
| Fails only when tests run in parallel | Workers sharing a database, cache, or file | Fix 2: Isolate Shared State, per worker |
| Fails near midnight, at a month boundary, or around a daylight-saving change | Time or date dependence | Freeze the clock in the test with jest.useFakeTimers() or Playwright’s page.clock |
| Fails only in CI, or only when a third-party service is slow | Timing under load, environment drift, or an external dependency | Fix 1: Replace Fixed Waits, then stub the external call |
Your product is the one cause outside every row. An intermittent failure can be a real race condition in the app, so before you rewrite a test, ask whether a user could hit the same failure. When the test is the problem, the next three sections fix the causes the table points to most often.
Fix 1: Replace Fixed Waits With Explicit Conditions
The classic flaky test guesses how long to wait instead of checking whether the thing it needs has happened. In UI suites that guess is the most common cause of all, and the fix carries across frameworks.
A 2021 study of 235 flaky UI tests from 62 projects traced about 45% of them to async waits, well ahead of the next cause, test-script logic, at 19%. Each pattern below swaps a timing guess for an explicit condition.
The Problem Pattern
// Flaky: assumes 2 seconds is enough
await page.click('#submit');
await sleep(2000);
const text = await page.textContent('#result');
expect(text).toBe('Order confirmed');
The 2-second guess fails when the server response takes 2.5 seconds under load, an animation delays element visibility, or network latency varies between environments. The wait was never tied to the thing it needed to wait for.
The Fix Pattern
Instead of guessing how long to wait, tell the test exactly what condition must be true before it moves on. The assertion below keeps re-checking the result element until it shows the expected text, and fails if its timeout runs out first.
// Stable: waits for the expected text
await page.locator('#submit').click();
await expect(page.locator('#result')).toHaveText('Order confirmed');
A common half-fix waits for the element to appear and then reads its text. If the element renders a placeholder like “Processing…” first, that read races the update, which is why Playwright’s own docs point text checks at toHaveText.
Advanced: Compound Conditions
Some actions need two things to happen before the test can go on. A form submission needs the API response to return and the UI to update. Promise.all starts listening for the response before the click fires the request, so a fast response can’t slip past the listener. The assertion after it then waits for the confirmation text.
// Wait for loading to complete AND element to appear
await Promise.all([
  page.waitForResponse(resp => resp.url().includes('/api/orders')),
  page.locator('#submit').click()
]);
await expect(page.locator('#result')).toContainText('confirmed');
Framework-Specific Patterns
Each test framework has its own idioms for stable async handling. Playwright has enough of them that flaky Playwright tests get a separate guide.
Playwright retries an assertion like toHaveText for 5 seconds by default, the expect.timeout value in its config. When a slow environment needs longer, raise the timeout on the assertion itself instead of adding a sleep.
await expect(page.locator('#result')).toHaveText('Order confirmed', {
  timeout: 10000
});
Cypress takes a similar approach with its built-in retry mechanism. The should assertion keeps checking until the element contains the expected text or 10 seconds pass.
cy.get('#result', { timeout: 10000 }).should('contain', 'Order confirmed');Selenium requires more explicit wait construction through WebDriverWait. You define the condition using Expected Conditions, and the driver polls until that condition returns true.
WebDriverWait(driver, 10).until(
    EC.text_to_be_present_in_element((By.ID, 'result'), 'Order confirmed')
)With Pie’s self-healing tests, your team authors supported tests in plain English, without writing a sleep(2000) or writing and maintaining a selector.
Fix 2: Isolate Shared State
Shared state is the flakiness I trust least, because it sails through code review and only detonates in CI. Two tests that write the same database row look independent until they run in parallel, and then which one wins changes from build to build. Multiply that across hundreds of tests and you get a suite where scheduling matters more than code quality. The path out is test isolation at every layer.
Database Isolation
Option 1: Transaction Rollback
Wrap each test in a transaction and roll it back afterward. Every INSERT, UPDATE, and DELETE gets undone when the test finishes. The next test starts with a pristine database.
@pytest.fixture(autouse=True)
def transactional_test(db_connection):
    transaction = db_connection.begin()
    yield
    transaction.rollback()
Rollback is fast because there’s no actual data to clean up, so the reset costs almost nothing. The limitation shows up when your test code opens multiple database connections, since each connection has its own transaction scope.
Option 2: Unique Data Per Test
Generate unique identifiers for all test data. Each test creates its own users, orders, and records with UUIDs or timestamps baked into the identifiers. Tests never collide because they’re operating on completely separate data.
const testId = `test_${Date.now()}_${Math.random().toString(36).substr(2, 9)}`;
const user = await createUser({ email: `${testId}@test.com` });
Unique test data works with any architecture, including microservices and distributed systems. It piles up, though, so you’ll need a periodic cleanup job to purge old test records, or your test database grows indefinitely.
Option 3: Dedicated Database Per Test Suite
Spin up isolated databases for parallel test execution. Each test worker gets its own Postgres instance, so there are no shared rows to collide on.
# docker-compose.test.yml
services:
  db-suite-1:
    image: postgres:17
    environment:
      POSTGRES_DB: test_suite_1
      POSTGRES_PASSWORD: test
  db-suite-2:
    image: postgres:17
    environment:
      POSTGRES_DB: test_suite_2
      POSTGRES_PASSWORD: test
True isolation comes at a cost. You need infrastructure to spin up and tear down databases, and each instance takes time to initialize. For large test suites running in parallel, the isolation is worth the setup overhead.
Cache Isolation
Redis, Memcached, and in-memory caches all persist data between test runs unless you explicitly clear them. So a test passes locally and fails in CI, where another test already filled the cache with stale data.
Option 1: Flush before each test
Wipe everything before each test starts. It’s simple and reliable, but slow if your cache is large.
beforeEach(async () => {
  await redis.flushall();
  await memcached.flush();
});
Option 2: Test-specific key prefixes
Each test worker gets its own namespace. Tests running in parallel never read each other’s cached values because they’re looking at different keys entirely.
const cachePrefix = `test_${process.env.JEST_WORKER_ID}_`;
cache.get(`${cachePrefix}${key}`);
Prefixing beats flushing on speed because it leaves other workers’ keys alone. It works as long as every cache operation in your test code applies the prefix.
Browser State Isolation
Login sessions, shopping carts, form data. Browser state accumulates across tests unless you explicitly reset it. A test that expects a logged-out state fails because a previous test logged in and never logged out.
Creating a fresh browser context for each test gives you a clean slate, with no cookies, localStorage, or session data carried over from previous tests. Playwright Test does this by default, because its built-in page fixture gets a new context for every test. When you manage contexts yourself, for example to sign in two users inside one test, newContext() gives each one an incognito-like isolated session.
// Playwright, two isolated users in one test
const userA = await browser.newContext();
const userB = await browser.newContext();
External Dependency Isolation
Third-party APIs are shared state you don’t control, and they hit API and integration suites hardest. A real payment gateway or partner API rate-limits you, times out, or returns a slightly different payload, so a Rest Assured or Supertest suite passes at 9am and fails at 2pm.
Stop calling the real thing in your test lane. Mock or stub every external dependency so the response is deterministic.
// Stub the flaky third-party call, assert on your own logic
nock('https://api.partner.com')
  .get('/v1/rates')
  .reply(200, { usd: 1.0 });
Keep one exception. A nightly, non-blocking contract job that hits the real endpoints and alerts when the contract drifts keeps the partner’s flakiness in one place and out of your PR builds.
Tired of Debugging Flaky Tests?
Write the test in plain English. No locators to break.
Fix 3: Break Order Dependencies
Run your test suite twice with different orderings. A test that passes in one order and fails in the other has an order dependency. They’re among the trickiest flaky tests to debug, because they show up only when execution order changes, which happens unpredictably in parallel CI runs.
Detection
Order dependencies pile up in suites that grew organically without strict isolation. A suite can pass for years because its tests happen to run in alphabetical order. Then someone turns on parallel runs and tests start failing for no visible reason.
Randomizing execution order drags these hidden dependencies into the open. The commands below shuffle the test order and print the seed, so you can replay a failing order later. Pytest needs the pytest-randomly plugin, and Jest’s --randomize needs version 29.5 or later and shuffles tests within each file.
# Pytest
pytest --randomly-seed=12345

# Jest
jest --randomize

# RSpec
rspec --order random
Run your full suite three times with different seeds. If any test fails inconsistently, investigate whether it depends on state created by another test.
Common Patterns and Fixes
Pattern 1: Test A creates data, Test B expects it
Test A creates a database record, and Test B queries for that exact record by ID. When A runs first, B passes. When B runs first, the record isn’t there yet and B fails. Make each test create and clean up its own data.
// Before (dependent)
test('A: create user', async () => {
  await createUser({ id: 1, name: 'Test' });
});

test('B: fetch user', async () => {
  const user = await getUser(1); // Assumes A ran first
  expect(user.name).toBe('Test');
});
// After (independent)
test('A: create user', async () => {
await createUser({ id: 1, name: 'Test' });
// Cleanup
await deleteUser(1);
});
test('B: fetch user', async () => {
// Create its own data
await createUser({ id: 2, name: 'Test' });
const user = await getUser(2);
expect(user.name).toBe('Test');
await deleteUser(2);
});Pattern 2: Global state modification
Global state, like a feature flag or a singleton, outlives the test that changed it. When one test flips a flag and doesn’t flip it back, every test after it runs in a polluted environment. Capture the original state before each test and restore it afterward, whether the test passes or fails.
// Before (modifies global)
test('A: enable feature', () => {
  featureFlags.enable('new_checkout');
  // Test with flag enabled
});

test('B: expects default state', () => {
  // Fails if A ran first and didn't reset
  expect(featureFlags.isEnabled('new_checkout')).toBe(false);
});
// After (isolated)
let originalFlags;
beforeEach(() => {
originalFlags = featureFlags.getAll();
});
afterEach(() => {
featureFlags.setAll(originalFlags);
});Retry, Quarantine, or Delete?
Quarantine is the right default for a flaky test you can’t fix today, and it beats the two options teams reach for instead. Left alone in a big end-to-end suite, flaky tests tend to get commented out, and the coverage goes with them. When a test flakes, you have three choices.
- Retry: Rerunning until it passes masks real bugs behind a green checkmark. It’s the worst default.
- Quarantine: The test stops blocking CI while its coverage intent stays visible.
- Delete: Correct only after quarantine has shown the test isn’t earning its keep.
Quarantine first, fix if the flow matters, delete if it doesn’t.
Implementation
Step 1: Tag flaky tests
Mark tests as quarantined in your code so tooling can find them. In Playwright, a tag does the job, and the run command can include or exclude it. Some teams prefer moving flaky tests to a separate directory entirely, which makes filtering easier in CI.
test('checkout flow', { tag: '@quarantine' }, async ({ page }) => {
  // Test code
});
The directory approach gives you physical separation. Everything in stable/ runs in the blocking CI job. Everything in quarantine/ runs separately.
tests/
  stable/
  quarantine/
Step 2: Run quarantined tests separately
Configure your CI pipeline to run stable and quarantined tests as separate jobs. Make the stable job a required check that blocks merges on failure. The quarantine job runs the tagged tests with continue-on-error: true, so flaky failures don’t block deploys while you work on fixes.
# GitHub Actions (checkout and install steps omitted)
jobs:
  stable-tests:
    runs-on: ubuntu-latest
    steps:
      - run: npx playwright test --grep-invert @quarantine

  quarantine-tests:
    runs-on: ubuntu-latest
    continue-on-error: true
    steps:
      - run: npx playwright test --grep @quarantine
Step 3: Monitor quarantine metrics
Quarantine without visibility becomes a dumping ground. Track these numbers weekly and display them on a dashboard your team sees daily.
- Quarantine size: Is it growing or shrinking?
- Days in quarantine: Which tests have been stuck the longest?
- Entry and exit rate: Are you fixing faster than you’re adding?
Step 4: Enforce quarantine limits
Cap how long a test can sit in quarantine. At 30 days it gets fixed or deleted, with no extensions. A fixed test goes back to the stable job once it passes a repeated-run loop sized to its old failure rate, using the table in the detection step.
Hold a weekly review where one named person takes each quarantined test and either commits to a fix date or deletes it. Slack’s system builds that accountability in by opening a ticket for every disabled test and assigning it to the team that owns it.
Preventing Future Flakiness
The fixes above repair tests after they’ve gone flaky. Prevention catches the same mistakes before the test merges. The patterns that produce flakiness are predictable: hardcoded sleeps, shared database records, implicit dependencies on test execution order. Baking prevention into your test architecture costs less than debugging intermittent failures at 2 AM.
Test Design Principles
Principle 1: No fixed sleeps
Ban fixed sleeps at the linter level, where a hardcoded wait fails CI before it becomes a flaky test. Enable the ESLint rule that matches your framework.
// Playwright (eslint-plugin-playwright)
rules: { 'playwright/no-wait-for-timeout': 'error' }

// Cypress (eslint-plugin-cypress)
rules: { 'cypress/no-unnecessary-waiting': 'error' }
For Testing Library suites, testing-library/prefer-find-by steers waitFor plus getBy toward findBy. It doesn’t flag a hand-rolled sleep() helper, so the git grep from the detection step remains your check for those.
Principle 2: Factory functions for data
Every test should create its own data using factory functions that generate unique identifiers. The factory below creates users with UUID-based emails so two tests can never collide on the same record. Overrides let a test set the fields it cares about and keep the generated defaults for the rest.
// test-utils/factories.js
export function createTestUser(overrides = {}) {
  return {
    id: uuid(),
    email: `${uuid()}@test.example`,
    createdAt: new Date(),
    ...overrides
  };
}
Principle 3: Environment parity
Tests that pass locally but fail in CI usually rely on environmental differences. Running your test database and cache in Docker makes your local environment match CI closely. Pin the Postgres and Redis versions in the compose file to whatever your CI runs.
services:
  app:
    build: .
    depends_on:
      - db
      - redis
  db:
    image: postgres:17
    environment:
      POSTGRES_PASSWORD: test
  redis:
    image: redis:7
CI Pipeline Hardening
The two patterns below stop flakiness at merge time. Handling flaky tests in CI/CD once they’re already in the pipeline, from parallel execution to quarantine workflows, is a bigger job with its own playbook.
Run new tests multiple times before merge
Catch flaky tests before they merge by running new or changed tests multiple times in CI. If a test passes on one run and fails on another, you catch the flake at the PR, before it reaches your main branch. This workflow runs only the tests affected by the PR, five times in a row.
# GitHub Actions (checkout with full history and install steps omitted)
on: pull_request

jobs:
  stability-check:
    runs-on: ubuntu-latest
    steps:
      - name: Run new tests 5 times
        run: |
          for i in {1..5}; do
            npm test -- --changedSince=origin/main
          done
Five runs catch a test that fails one run in ten only 41% of the time. The loop stops loud flakes at the PR, and the failure history from detection catches the quiet ones later.
Block merge on flaky detection
Once your reporter emits a flaky rate, gate merges on it. The script below assumes your pipeline writes that rate, as a whole-number percentage, to test-results/flaky-rate.txt. It fails the build if more than 5% of test runs were inconsistent, keeping PRs that introduce new flakiness from merging.
- name: Check flaky rate
  run: |
    if [[ $(cat test-results/flaky-rate.txt) -gt 5 ]]; then
      echo "Flaky rate above 5%, failing build"
      exit 1
    fi
Three Team Habits
Architecture won’t hold if your team treats flaky tests as someone else’s problem. Three habits keep flakiness visible and owned.
- Boy Scout rule: When you hit a flaky test during unrelated work, give it 15 minutes. Fix it if you can, and if you can’t, log what you learned in the backlog.
- Flaky Test Friday: Put the weekly quarantine review from Step 4 in a fixed Friday hour and rotate who runs it. A month of its log tells you more than any single week.
- No blame for writing one: Penalize the engineer who wrote a flaky test and the next flake gets rerun until green and never reported. Put the pressure on tests that sit unfixed in quarantine.
Measuring Progress in Four Numbers
Four numbers tell you whether the flaky backlog is shrinking or just moving into quarantine. Track them monthly, and treat the targets as starting points to tighten as the suite improves. Without them, a flaky-test discussion turns into finger-pointing.
| Metric | Target | How to Measure |
|---|---|---|
| Flaky test rate | <2% | Failures without code change / total runs |
| Quarantine size | <5% of suite | Quarantined tests / total tests |
| Mean time to fix | <48 hours | Time from flaky detection to merge |
| CI false positive rate | <1% | Builds failed for non-code reasons |
A number that moves the wrong way two months running deserves the same treatment as a failing test. Give it an owner and a date.
What Pie Does About Flaky Tests
All of those fixes live in test code your team writes and maintains. A fixed sleep and a pinned selector are both guesses about the page, and a supported Pie test doesn’t need either one written.
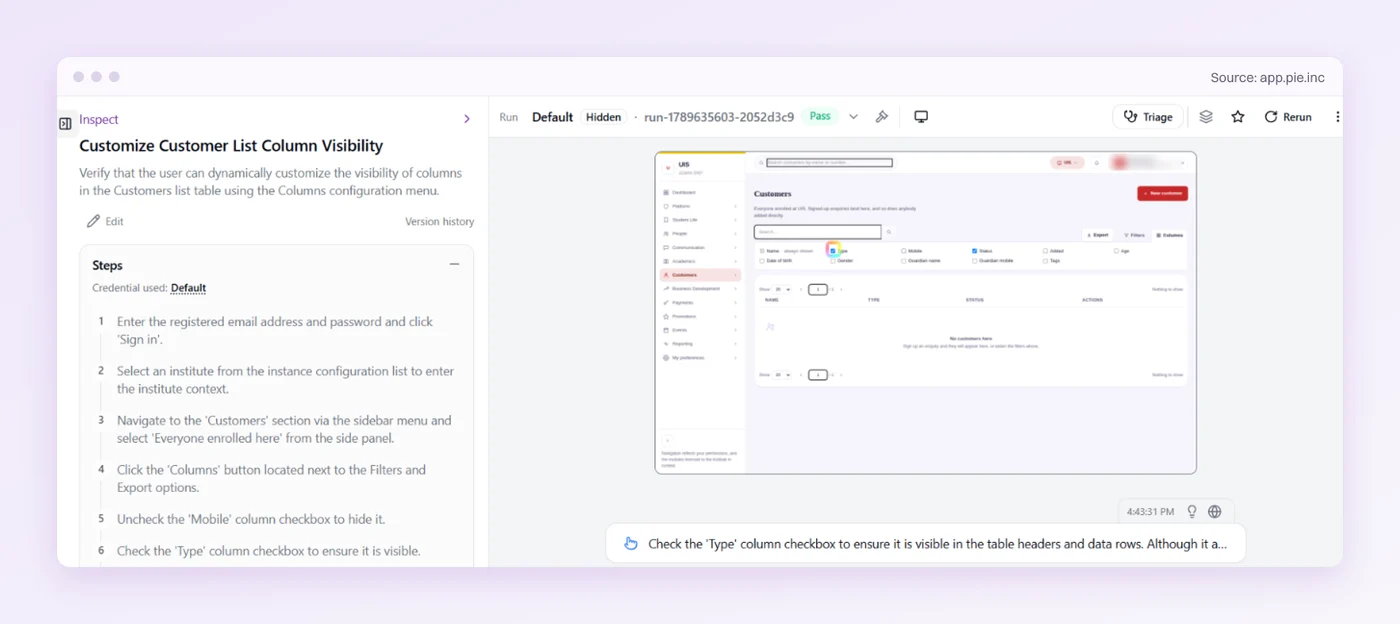
- Plain-English steps: Your team authors supported tests without writing a
sleep(2000)or writing and maintaining selectors. - Vision-first runs: Pie executes each step vision-first, reading the screen the way a person would.
- Nothing authored to patch: Some AI testing tools self-heal by patching a locator your team wrote once it stops matching. A Pie test starts from plain-English steps, so there’s no hand-written locator to patch.
If your UI suite grows faster than you can triage it, hand those tests to Pie first.
Fix Today’s Flakes, Then Stop Writing New Ones
Every flaky test that blocks a deploy costs more than the hour you spend investigating it. It costs the trust that makes continuous deployment work. When engineers stop believing red builds, they start ignoring them, and that’s when real bugs ship.
The fixes in this guide clear the flaky tests you already have. They don’t stop the next batch from arriving.
We built Pie for the next batch. For the UI tests Pie runs, nobody on your team has to write the waits and selectors flaky tests lean on, and a red build starts meaning something again.
Less Maintenance. More Shipping.
Skip the hand-coded waits. Spend the hours shipping.
Frequently Asked Questions
Detect, fix, then prevent. Track pass and fail history to find the tests that flip, then fix each one at its cause, usually an async wait, shared state or test order. Stop new ones at merge with a lint rule and repeat runs on new tests. Retrying hides the problem.
Replace implicit and fixed waits with an explicit WebDriverWait tied to a real condition, and start each test from a fresh browser session. Selenium has no built-in equivalent of Playwright's actionability auto-waiting, so you add the explicit waits yourself. Quarantine what you can't fix yet.
Quarantine first, then fix or delete. Retrying until green hides real bugs. Quarantine moves the test to a non-blocking lane while you diagnose it. At 30 days, fix it or delete it, and delete it if it covers nothing critical. A test nobody trusts is worse than no test.
Rerun it on the same commit. If the result flips, it's flaky. If it fails every time, it's a real bug or a broken test.
Ten reruns catch a test that fails one run in ten about two times in three, so a rarer flake needs dozens of runs.
CI runners often have fewer resources, different timing, and no cached state from earlier runs. Tests that depend on fast responses, leftover database records, or browser cookies pass locally and fail there. Replace fixed waits with explicit ones and give every test its own isolated data.
Rank by blast radius. Fix flaky tests on critical flows like checkout and login first, especially at a 10% failure rate or higher. Quarantine non-critical ones and schedule the fix. Fix or delete tests that reach the 30-day quarantine deadline.
They can add to the problem. More generated code means more tests to flake, and a 2026 study of LLM-generated database tests found a slightly higher flaky share than existing tests, with models copying flakiness from their prompt context. Fix the tests your assistant copies from first.
Pie tests are plain-English steps that Pie runs vision-first, reading the screen the way a person would. Your team authors supported tests without writing a fixed sleep or writing and maintaining selectors, so the timing guesses flaky UI tests lean on don't have to be written.
13 years building mobile infrastructure at Square, Facebook, and Instacart. Now building the QA platform he wished existed the whole time. LinkedIn →