Test Automation Strategy: What to Automate First, in Order
Every check looks worth automating, and no team can keep them all green. This test automation strategy ranks what to automate first and where to stop.

Your regression sheet runs to a couple of hundred checks, and every row is marked high priority. The quarter has room to script a few dozen. Choose badly and the suite spends the next sprint breaking on screens that moved.
Ranking is the core of a test automation strategy. Here is how to rank your own sheet so the checks you script pay back, and how to tell which ones belong with your testers.
What you’ll learn
- The order to automate in, from the cheapest check to the costliest
- Four questions that place any check on that order
- Where to stop on each rung, and which checks stay with your testers
- The two events that re-rank the order
Six Rungs, Ordered by Payoff Against Upkeep
A test automation strategy is a ranked order of what to script, with a stop line on every step. Automate in order of payoff against upkeep. A check pays off by running often and protecting a lot, and its upkeep depends on how often its screen changes. A rung opens only when the one beneath it runs green without repair.
| Rung | What to automate | Usual owner | Stop line |
|---|---|---|---|
| 1 | Unit tests on logic that has already broken | Developers | Every fixed bug leaves a test behind |
| 2 | A smoke check on every build | Developers or QA | It signs in and reaches the core screen, nothing more |
| 3 | API and service checks | Developers or QA | Each service contract has one check |
| 4 | End-to-end flows that earn or lose money | QA | Every flow whose break would page someone has a test |
| 5 | Regression on steady screens | QA | The repeat pass is gone for those screens |
| 6 | Data combinations and device matrices | QA | A check costs more to keep than a miss costs |
Rungs one to three usually belong to developers, so a QA lead’s first move is to check that they exist. The part of the strategy a QA team owns starts at rung four.
Four Questions That Place Any Check
Every row on a regression sheet can be placed by four questions asked in order. They extend the placement rule from our comparison of manual vs automated testing, with the cost of a miss added as the sort key.
- Frequency: Does the check run every release? One that runs twice a year never repays its script, so it stays manual.
- Clear result: Is there one expected result a script can read? A cart total that matches its line items is a yes. A page that feels right is a no, and a person answers it.
- Cost of a miss: What does it cost when this breaks? Lost sales, lost trust and safety rank highest. Sort the checks that survived the first two questions by this, highest first.
- Screen churn: Is the screen it touches steady? A steady screen takes a script. A screen that changes every sprint waits, or goes to a tool that does not depend on selectors.
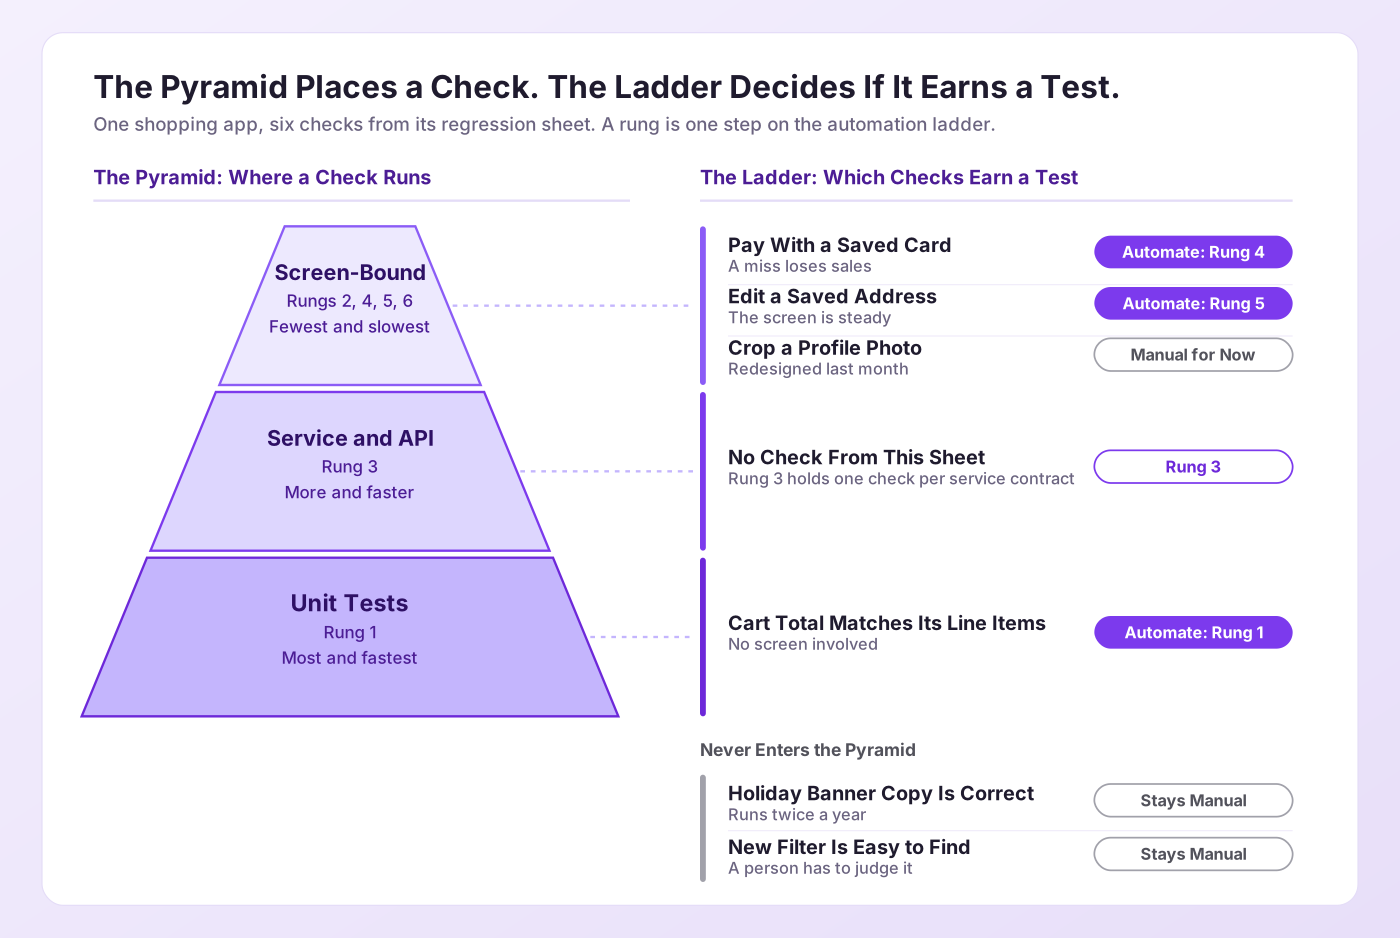
Take a shopping app. Six checks from its regression sheet land in four places, and the cart total drops to the base of the ladder because it never needed a screen.
| Check | Question it fails | Lands on |
|---|---|---|
| Cart total matches its line items | Nothing, and no screen is involved | Rung 1 |
| Pay with a saved card | Nothing, and a miss loses sales | Rung 4 |
| Edit a saved address | Nothing, and the screen is steady | Rung 5 |
| Holiday banner copy is correct | Frequency, it runs twice a year | Manual |
| New filter is easy to find | Clear result, a person must judge it | Manual |
| Crop a profile photo | Screen churn, redesigned last month | Manual for now |
What Each Rung Buys and Where to Stop
Each rung has a reason to sit where it does and a point past which more checks cost more than they return. The bottom of the ladder follows a rule Ham Vocke gave in The Practical Test Pyramid:
“Push your tests as far down the test pyramid as you can”
Ham Vocke, martinfowler.com, 2018
The pyramid settles where a check runs fastest. It does not settle how many end-to-end flows to keep. Here the cost of a miss and how often a screen changes decide that.
- Past-bug unit tests: No screen is involved, so almost nothing breaks them. When a higher-level test catches a bug and no unit test fails beneath it, Vocke’s advice is to write the lower-level test. Jest, pytest and JUnit cover the common stacks. Make it a standing rule that every fixed bug leaves a test behind.
- Build smoke check: A short smoke test that signs in and reaches the core screen tells the team within minutes that a build is dead. Stop at the first screens a user meets, because a smoke suite that keeps growing turns into a slow regression suite.
- Service checks: Calls to your API run beneath the screens, so a screen redesign leaves them alone. One check per contract between services is enough, written in the same runner the developers already use.
- Money flows: Sign-up, sign-in, checkout and the one action customers pay for. There are only a few, and each one guards a lot. They are the best use of a slow, screen-bound test. Rank them by cost of a miss and stop when each flow that would page someone has one test.
- Stable-screen regression: The repeat pass your testers click through every release is where scripting returns the most tester time, and where upkeep bites hardest. As I see it, the real cost of an end-to-end suite is engineering time. You spend it once to write each test and again to keep it current as the code base grows. Begin with the screens that have stayed put longest, and read how to automate regression testing for the steps.
- Wide coverage: Data combinations, device matrices and rare edge paths multiply checks fast. Each one is another test to keep current and another result someone has to read. My advice is to grow this rung only as fast as your team can review what it reports. Ramp up faster and nobody has the bandwidth to read the results. Close the rung when a check costs more to keep than a miss would cost.
Name the Flows That Matter
Pick the flows that would page someone. Pie writes and runs their tests.
What Stays With Your Testers
Ranking by payoff leaves a list of checks that never earn a script, and that list is your manual team’s brief. Every hour that automation takes off the repeat pass goes to these checks.
- Exploratory testing: A tester follows a hunch into a corner no written path reaches. Exploratory testing finds what a suite never thought to ask.
- Usability and feel: Whether a button sits where people look is a judgment, and a script can only confirm that the button exists.
- Features mid-build: When expected behavior changes every few days, a script written today is rewritten next week.
- First pass on new work: A person runs a new feature once before anyone scripts it, and that run shows which checks deserve a script.
- Device-in-hand checks: Pairing a physical product or pointing a camera at something stays with a person holding the device.
- The final call: Whether a release does what the business asked is a human decision.
Two Triggers That Re-Rank the Ladder
The order holds until one of two things happens, and both show up in the suite itself.
- Screen churn: A screen starts changing every sprint. Its checks leave the scripted rungs, because a script finds each element by something written into the page and a redesign breaks it. Keep those checks manual until the screen settles.
- Noisy failures: Red runs stop meaning bugs. Martin Fowler’s test pyramid note warns that end-to-end tests are more prone to non-determinism, which can undermine trust in them. Once a rung’s failures are noise, freeze every rung above it until a red run means a bug again.
Write the Strategy on One Page
A test automation strategy fits on one page, with four lines on it:
- Rungs funded: Which rungs get checks this quarter.
- Owners: One named owner per rung.
- Stop lines: Where each rung stops growing.
- Triggers: The two events that send the page back for review.
Tool choice and CI wiring belong in the plan as well. They follow from the order. Once rung four is next, you know which flows your test automation tools have to drive.
Hand the Screen-Bound Rungs to Pie
Rungs four and five sit on screens, and they are the part of the ladder a QA team owns. Our agentic testing platform writes and runs the tests for those rungs on web, iOS and Android, while your developers keep rungs one to three.
- Upkeep handled for you: Pie explores your app and generates the tests, and they self-heal. A changed selector does not break them, so your team is not repairing scripts after every redesign.
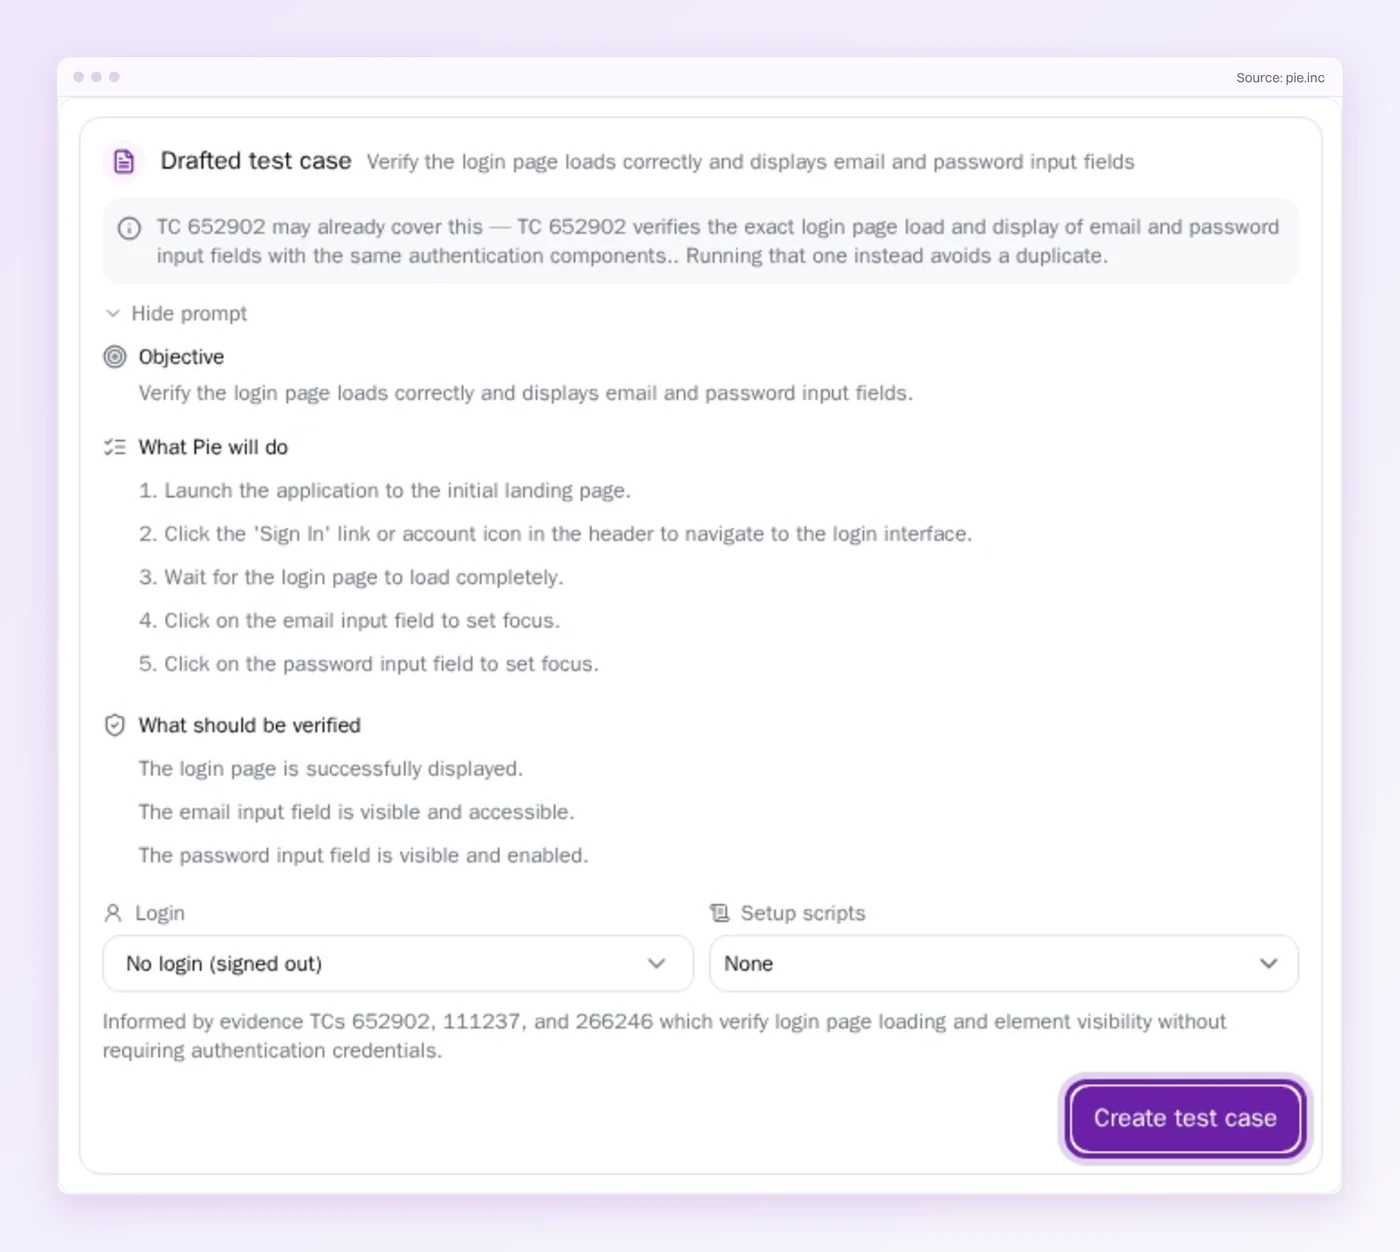
- Checks from a sentence: Describe a manual check in Pie Chat and review the draft before it runs.
- A map to rank against: Pie groups the tests it writes under your app’s key features, so the money flows from rung four are easy to find.
- Testers stay in charge: Pie works alongside a manual QA team and your unit tests. It adds to both and replaces neither.
Climb in Order and Stop on Purpose
The order is the strategy. Four questions place each check on a rung, and every rung has a line where it stops growing. A small ladder that stays green beats a large suite nobody trusts.
Open your sheet and find the row whose failure would page someone tonight. Does it have a test yet?
Script what pays. Leave the rest to people who can think about it.
Spend Testers on Judgment
Hand Pie the screen-bound rungs. Keep your testers on the hard calls.
Frequently Asked Questions
Spent a decade in B2B SaaS sales before building Pie. Now obsessed with helping engineering teams ship without the fear of breaking things. LinkedIn →