Testing AI-Generated Code: What Actually Catches the Bugs
AI models write code that runs far better than code that is safe. How to test what they write, why their own tests miss, and what scales as volume climbs.
An AI coding agent sees only the files it has read. It does not see the three other files your change is about to break, or the assumption the service on the other side is quietly making. The function compiles, the unit test passes, and the break shows up somewhere the agent never looked.
Models keep getting better at writing code that runs and have barely moved on writing code that is safe. Veracode’s 2026 benchmark puts the average security pass rate across more than 100 models at 56%, a rate that has not improved since the report’s first edition. Test that output the way you tested hand-typed code and you miss those bugs. Testing behavior catches them.
What you’ll learn
- The four failure modes where AI-generated code consistently breaks
- Five concrete tactics that catch AI bugs, and why AI writing its own tests backfires
- Which validation methods hold up as AI code volume climbs
- How to keep QA capacity from becoming the bottleneck
Where the Time Goes When AI Writes the Code
In early 2025, METR ran a randomized trial with 16 experienced open-source developers in codebases they knew well. They forecast a 24% speedup. Afterward they believed AI had sped them up by 20%. Measured, they took 19% longer, a 39-point gap between feeling and clock.
In February 2026, METR revisited that result. Speedups now look likely, and the follow-up ran into a new problem. Between 30% and 50% of its developers said they kept some tasks out of the study because they would not do them without AI. So take the speed as real. It moves the work somewhere else.
Harness’s 2026 State of Engineering Excellence survey found that 81% say developers spend more time in code review since adopting AI coding tools. The speed shows up in the writing and leaves again in the checking.
Vibe coding is great in the moment. Describe what you want. The model writes it. You ship. Checking the code is now the constraint. Using Cursor, Copilot, or Claude Code well includes changing how you test.
Four Ways AI-Generated Code Breaks
AI-generated code fails in predictable places, and knowing the places is what makes it testable. Four come up again and again. They cluster, and targeted testing beats blanket coverage for exactly that reason.
- Context blindness. The model works from the context it was handed, almost like a contractor renovating one room without the floor plan. Your architecture, your conventions, and the caller two services away sit outside it. The function runs. The integration breaks, and no test that checks the function in isolation will see it.
- Confident incorrectness. Humans hedge. Models do not. AI produces plausible, professional-looking code with total confidence whether it is right or wrong. Obvious errors get caught in review. Subtly wrong code that reads clean slips straight through.
- Security blind spots. Training data mixes vulnerable patterns with secure ones, and the model does not reliably tell them apart. SQL injection, XSS, broken auth, and missing input validation all appear when they fit the context. Veracode’s finding that the pass rate barely moved across a year of new models is this failure mode measured.
- The test-coverage illusion. AI can write tests, which sounds like the solution and is usually a trap. AI-generated tests tend to share the same misunderstanding as the code they check. If the model misread the requirement once, it misreads it twice, and the test agrees with the bug. Because AI that writes tests inherits that misreading, the check has to live outside the model that wrote the code.
How to Test AI-Generated Code in Five Steps
Testing AI-generated code well means validating behavior against a definition of correct that the model did not author. That single principle separates the tactics that work from the ones that just make you feel covered. Five pass that test.
- Write the failing test first. Define expected behavior in a test before you prompt for the implementation. The model then works against a specification it cannot redefine to match its own output. If the agent edits that test later, read the diff first. A loosened assertion turns red to green without fixing anything.
- Reach for property-based testing. Hypothesis in Python and fast-check in JavaScript generate random inputs against rules that must always hold, 100 per property by default (
max_examplesin Hypothesis,numRunsin fast-check). They surface the off-by-one and boundary gaps that example-based tests skip, and models skip the same ones. - Try to break it on purpose. Feed AI code the inputs it did not consider. Null and empty values, extreme numbers, Unicode, injection strings. This is negative testing, and it maps directly onto the confident-incorrectness failure mode above.
- Gate merges on a security scan. Static analysis and scanners like GitHub CodeQL catch known vulnerable patterns cheaply. With AI code security stalled for a year, the scan belongs in the pipeline as a required check. Have the pipeline also flag any new dependency your team has not vetted, because models invent package names that attackers can then register.
- Validate the behavior end-to-end. Unit tests confirm the code does what the code thinks it should. Only exercising the real user flow confirms it does what the user needs. Context-blindness bugs surface here and almost nowhere else, which is where autonomous QA catches what code-level checks miss.
Steps 1 through 4 harden the code. Step 5 checks the experience, and it is the easiest step to drop when a sprint runs long. Integration is where AI code fails hardest, so if you keep one step from this list, keep the last.
Which Validation Methods Hold Up
No single method handles AI-generated code on its own, because each catches a different class of problem. The useful split is whether a failure lives inside the change or in the system around it. Static analysis and review own the first. Only something that runs the product owns the second, and plenty of AI test automation tools bolt a model onto one row of this table without changing which work it removes.
| Method | Catches | Misses | AI-Code Fit |
|---|---|---|---|
| Human code review | Architecture, business logic | Subtle bugs; scales poorly at high volume | Partial |
| Static analysis / SAST | Syntax, known security patterns | Runtime behavior, integration bugs | Partial |
| Property-based testing | Edge cases, boundary conditions | Cross-service and UX behavior | Strong (for logic) |
| Traditional selector-based E2E | User flows when tests hold | Breaks often as AI regenerates UI | Poor |
| Autonomous QA | User-level behavior; can adapt to UI changes | Requires initial setup and a staging URL or app build | Strong |
Traditional end-to-end testing deserves a specific warning. It finds elements through selectors, and when AI regenerates UI code often, those selectors change often and tests break. The team ends up spending more time fixing tests than the tests save. Self-healing tests sidestep the trap by identifying elements through context. A moved button can be found again without failing the run.
Why QA Capacity Breaks First
Defect density per line gets the debate. Total volume against a fixed QA team does the damage. Even at a comparable defect rate, more code means proportionally more bugs arriving at a process that did not grow. Put three numbers next to each other.
- Volume: GitHub’s 2025 Octoverse counted 43.2 million merged pull requests a month, up 23% in a year.
- Safety rate: Veracode’s 2026 benchmark found the average security pass rate on AI-generated code stalled at 56%.
- Verification: In Sonar’s January 2026 survey, 96% of developers said they do not fully trust AI-generated code, and only 48% always verify it before committing.
More code, a near-flat safety rate, and a verification step fewer than half of developers always run. Whether AI code carries more bugs per pull request is a separate argument, and the capacity math breaks the same way whichever side of it you land on. You cannot review your way out of that one pull request at a time, and hiring linearly against compounding volume does not close it either.
Keep QA in Step With AI Code
Hand Pie your staging build. Get back the flows nobody had time to check.
A Validation Stack That Scales
A validation pipeline for AI-generated code layers automated checks so human judgment lands only where it is needed. Here is the shape that works when your team ships AI code at real volume.
- AI writes the code through Cursor, Copilot, or Claude Code.
- Static analysis and security scans catch syntax and known vulnerable patterns automatically.
- Property-based and unit tests exercise logic and edge cases, written against a spec the model did not author.
- Autonomous QA explores the running app and validates the actual user experience across flows.
- Your team makes the ship call, reading findings from the running app instead of every diff.
The four automated layers scale with code volume. The human layer is the one you do not want to scale, and the arrangement exists to keep it that way. Teams that let the checks make the merge call too are running a software factory, and these layers become its stations. We built Pie for the fourth layer. Its agents run autonomous discovery over the reachable flows in your web or mobile app, execute vision-first, and can keep checking the same behavior when the markup underneath them changes. Fi, the smart pet collar company, runs it on web and mobile.
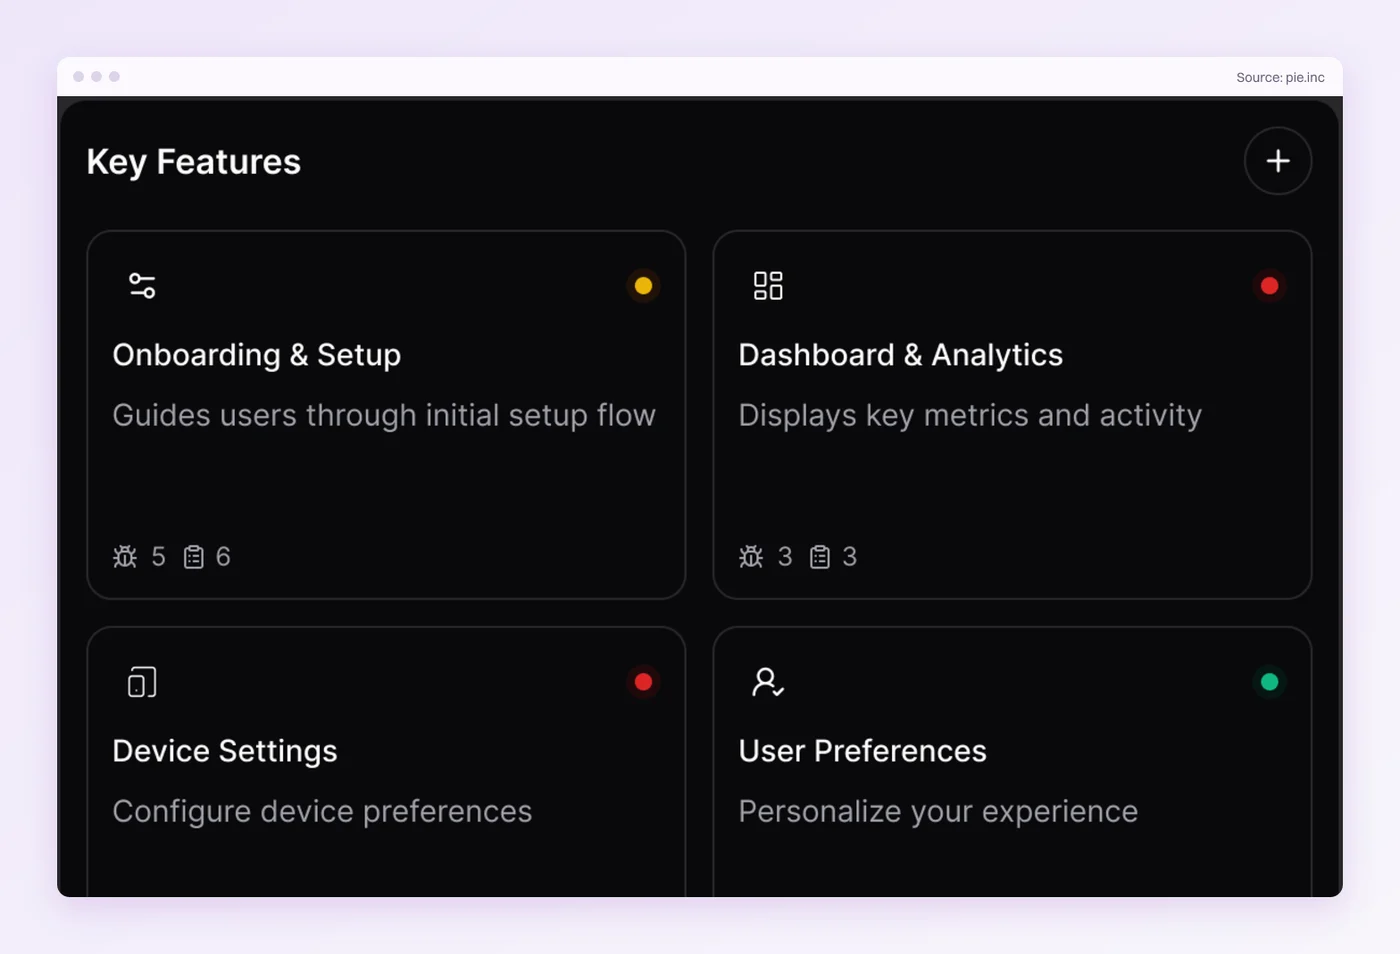
Three things change about how the team runs, and none of them is “test less.”
- Shift left, partway. Static analysis and code review at the pull-request level catch problems early, which matters more when volume is high. They are necessary and not sufficient, because AI bugs often surface only at integration. Keep end-to-end validation in staging before every release.
- Budget validation to scale. If AI made writing several times faster, validation has to keep pace, and that does not mean several times the QA headcount. Automate the validation that needs no human judgment, and the team you have can cover the code volume you now produce.
- Redefine the QA role. Manual testers cannot click through that much code by hand. Their judgment is the scarce resource, not their clicking. The role grows from execution into strategy and final verification. Which flows matter most, and is this safe to ship?
Where the Bugs Live Now
TLDR, AI made your developers faster at producing code. It did not make the code correct, and it did not make your QA any faster.
That gap is where the bugs get through. They live in the running product, where a function can pass every unit test and break the flow that pays your bills.
Pie tests that layer, working through your web or mobile app the way a customer does. Write with AI, and ship what already worked.
Stop Guessing What AI Broke
Ship the code your agent wrote. Know what it broke before release day.
Frequently Asked Questions
Test what the code does. Write the failing test before you prompt, add property-based tests for edge cases, make a security scan a required check, and run the real user flow end to end.
Never let one model write both the feature and the tests that check it.
Yes, with a blind spot. Tests the model writes tend to share the misreading behind the code they check. The two agree, and both are wrong.
Use AI-written tests for coverage on low-risk utility code, and check critical paths against a spec the model did not write.
Detector tools exist, and none of them tells you whether the code works. Knowing a function was AI-written says nothing about whether it handles a null input or leaks a token.
Run the same behavioral checks on every change, whoever or whatever wrote it.
Per pull request, the gap is still debated. Per team, yes, because volume is the bigger shift.
Veracode's 2026 benchmark puts the average security pass rate of AI-generated code at 56%. More code at a near-flat safety rate means more bugs reach a QA team that did not grow.
No. The tools pay off when validation scales with them, and slowing generation to match a manual QA process throws away the one gain they gave you.
AI writes the code, automated QA checks the experience, and your team makes the ship call.
Pair static analysis with runtime checks. Scanners like GitHub CodeQL catch known vulnerable patterns, and auth and input-validation gaps often surface only when the code runs.
Veracode's 2026 benchmark shows the security pass rate of AI code barely moved in a year. Make the scan a required gate.
Yes, at the layer your users see. Pie's agents explore the reachable flows of your web or mobile app and execute vision-first, so you can author supported tests without maintaining selectors.
A regenerated UI does not have to mean a rewritten suite, and the release decision stays with your team.
Eight years building search and delivery systems at Amazon. The kind of scale where flaky tests block billion-dollar releases. Now CTO at Pie, building AI agents that adapt when your UI changes. LinkedIn →